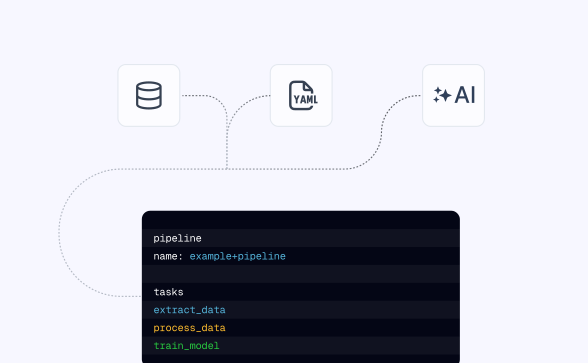
Build data and AI pipelines declaratively
Dagster Components let any stakeholder write a few lines of YAML to create production ready data pipelines.
Your data platform shouldn’t feel like rocket science. Onboard teams to your data platform while enforcing standards with declarative data pipelines.
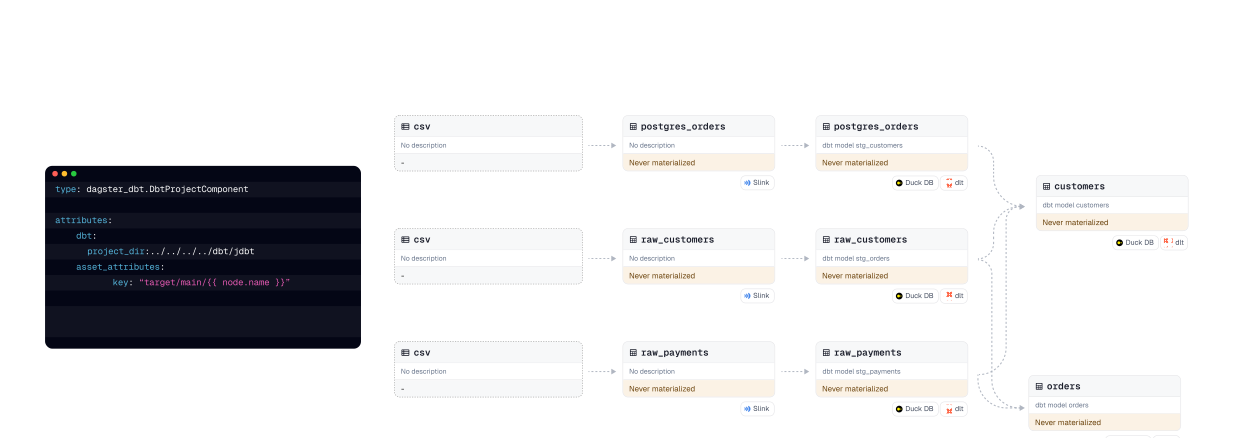
Dagster Components takes your Python code and makes it reusable and configurable
Dagster Components let any stakeholder write a few lines of YAML to create production ready data pipelines.
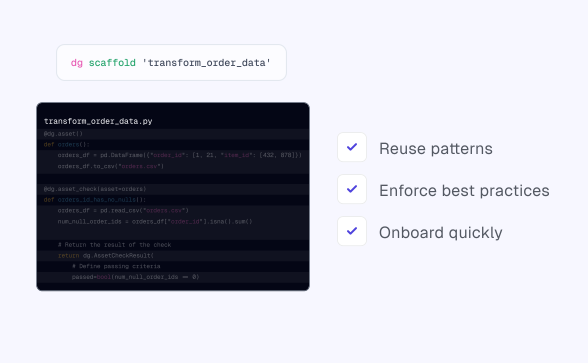
Build custom components that abstract away glue code, so teams can reuse patterns, enforce best practices, and onboard quickly.
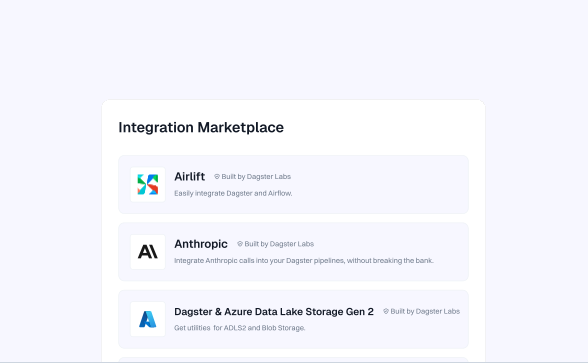
We include many out-of-the-box Components for common data technologies like dbt. Coming soon, you can publish your organization’s custom Components to a private component library right inside of Dagster+.
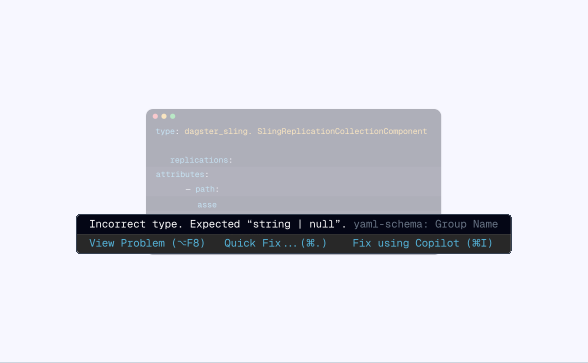
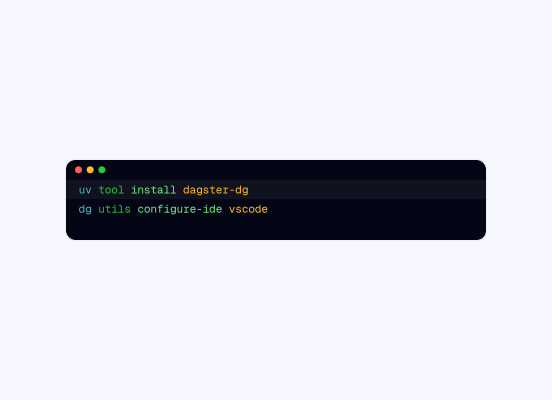
A powerful but approachable CLI, full IDE autocompletion support, and rich error reporting should be table stakes. Components ship with all that and support for Model Context Protocol so that you can fully leverage AI code generation.
A developer experience that actually delivers on the promise of elegance, simplicity, and productivity in a modular framework.
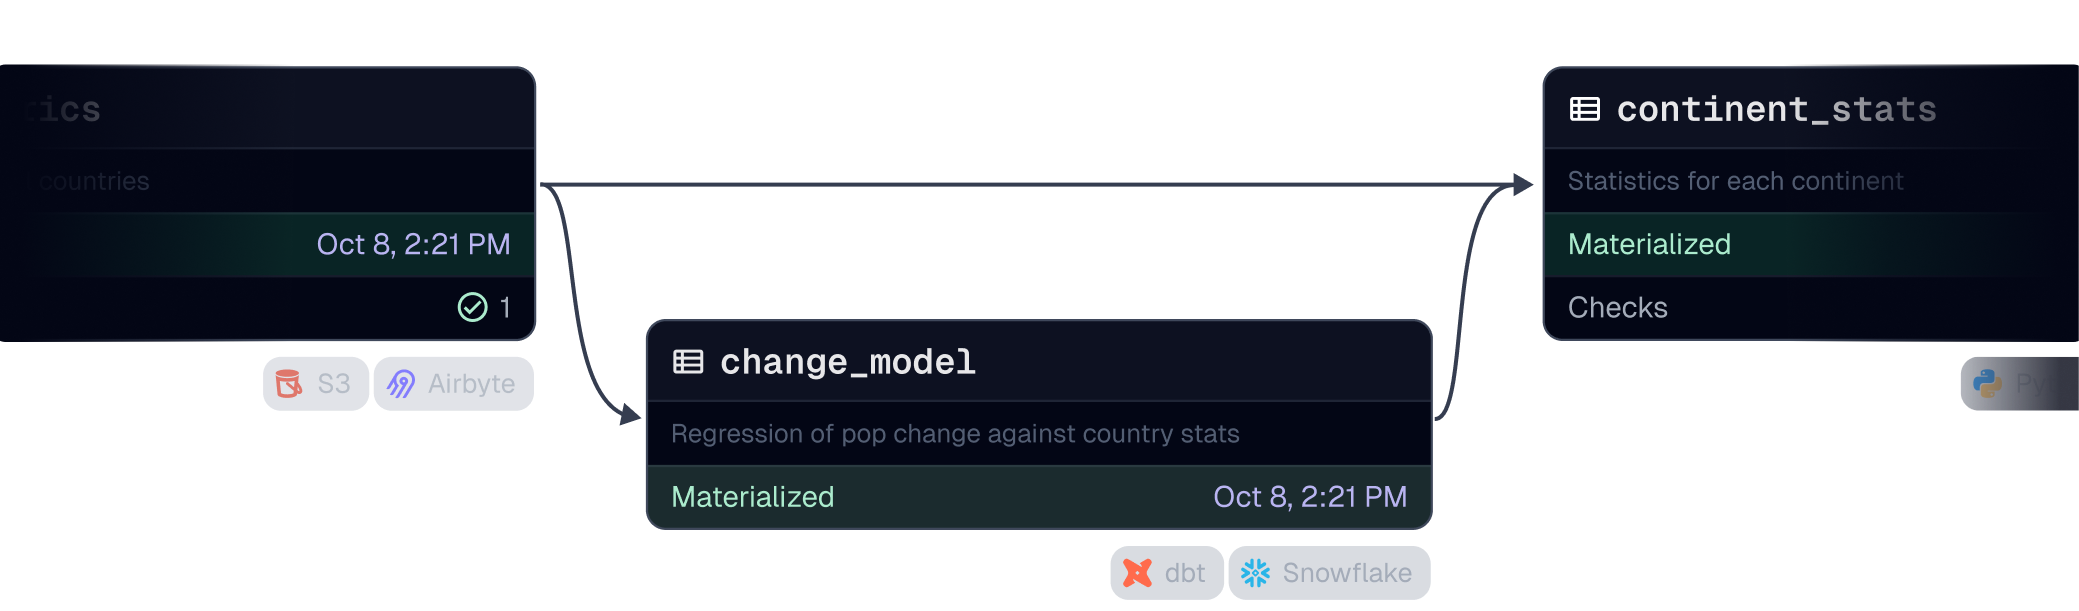
Stop wasting engineering time on repeated. Enable your downstream teams to write their own pipelines. No glue code, no retraining. Out-of-the-box support for dbt, Fivetran, DLT, Snowflake, Power BI and more.
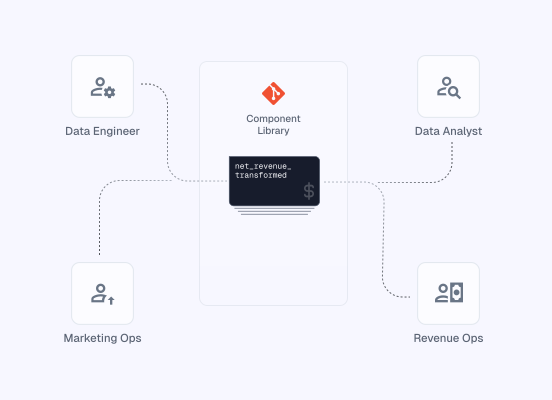
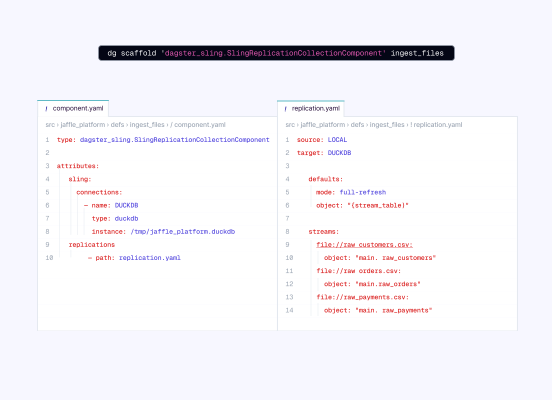
Dagster enables data platform teams to standardize best practices by authoring reusable Components. Teams using these Components can rest assured that they're building with best-practices in mind.
Building new pipelines is pain free with self-documenting components, IDE autocompletion, and component validation with detailed errors. Components eliminate boilerplate, and the built-int Model Context Protocol (MCP) support enables you to take advantage of all the benefits of AI, with full safety guardrails.
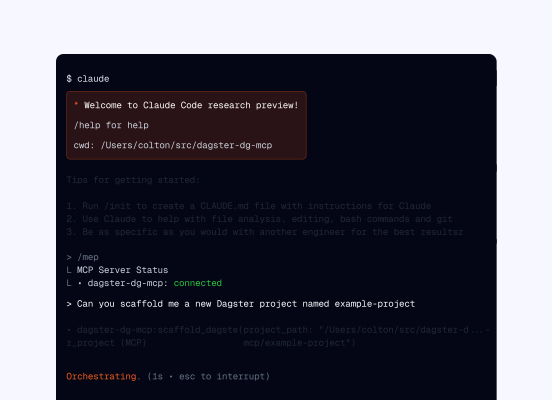
Components make data pipeline code so simple, even AI could write it. With defined schemas, your components are easy to build with modern AI developer tooling.
Dagster Components was designed with modern data teams in mind, supporting software development best practices such as infrastructure-as-code, GitOps, CI/CD, local development, and branch deployments.
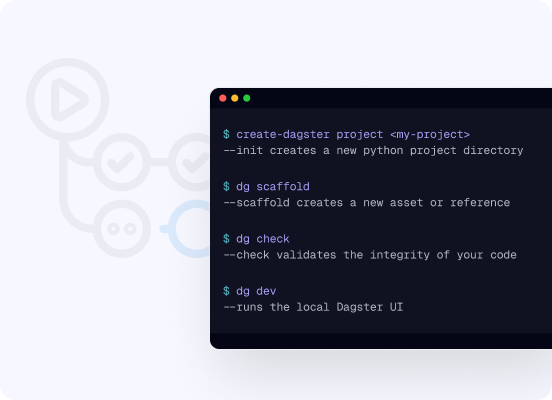
Great data engineering starts with the right tools, built by experts who understand modern data pipelines.
Get the best of both worlds with YAML for simple configurations and Python when complex use cases demand it.
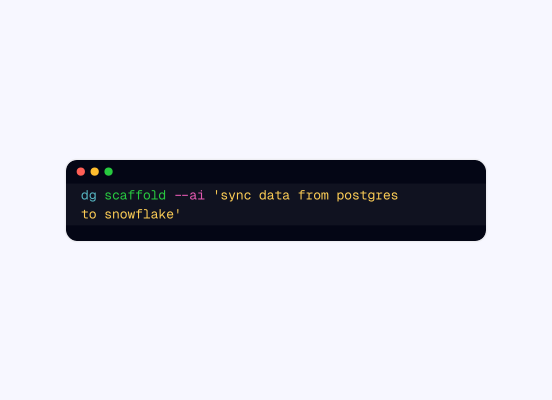
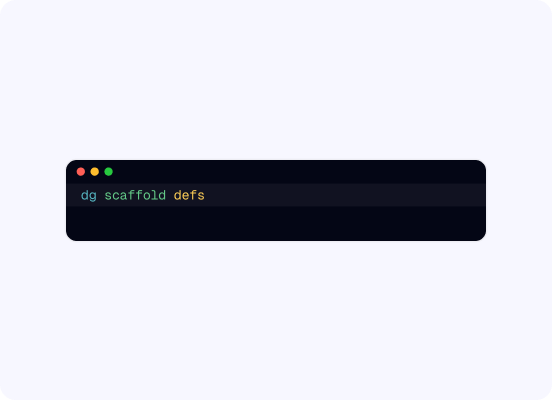
Spin up a ready-to-run Dagster project in minutes without boilerplate.
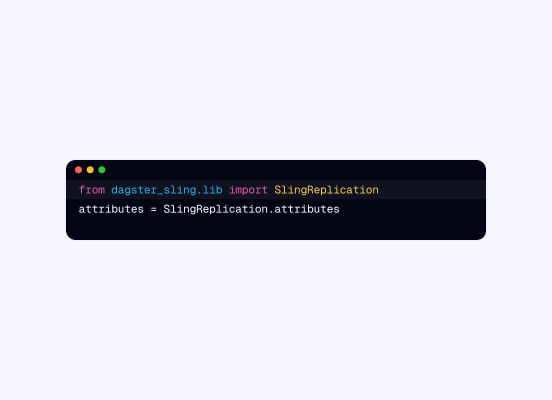
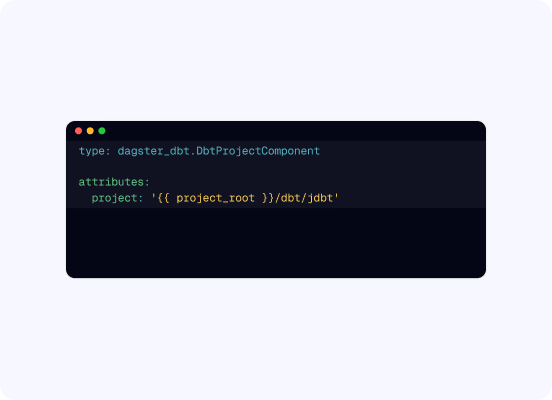
Edit your YAML file to ensure that all the details are correct and that the pipeline does exactly what you want it to.
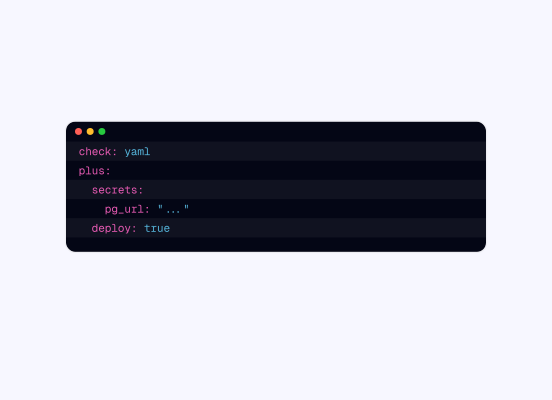
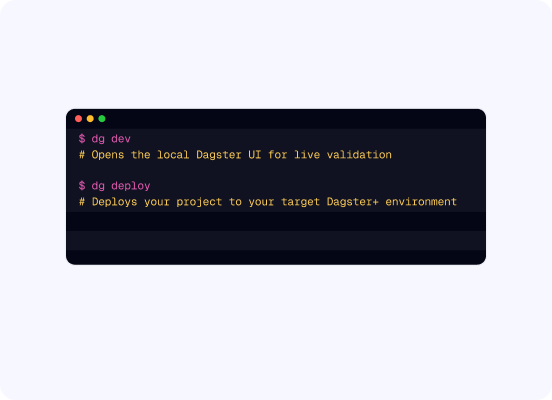
Instantly validate that your YAML is correct, manage your secrets, and deploy with a single command.
"Dagster is easy to use, it's ELT friendly, can integrate with the main modern tools out of box and allows you to automate whatever you want wherever it is."
"We would not exist today as a company if we didn't move to a single unified codebase, with a real data platform beneath it."
“Somebody magically built the thing I had been envisioning and wanted, and now it's there and I can use it.”
“Dagster has been instrumental in empowering our development team to deliver insights at 20x the velocity compared to the past. From Idea inception to Insight is down to 2 days vs 6+ months before.”