Orchestration is More than Scheduling: Declarative Automation in Dagster
Define the outcome, not the orchestration. Declarative Automation lets you express your desired asset state while Dagster continuously handles the work needed to achieve it.
Showing 12 of 187 articles.
Define the outcome, not the orchestration. Declarative Automation lets you express your desired asset state while Dagster continuously handles the work needed to achieve it.
Some of the most interesting Dagster projects come from the community. This post highlights creative community-built applications.

data governance. I built a tiered AI classification system, human review workflow, and the Dagster orchestration that ties it all together in production in nine days.
Some of the most interesting Dagster projects come from the community. This post highlights creative community-built applications.
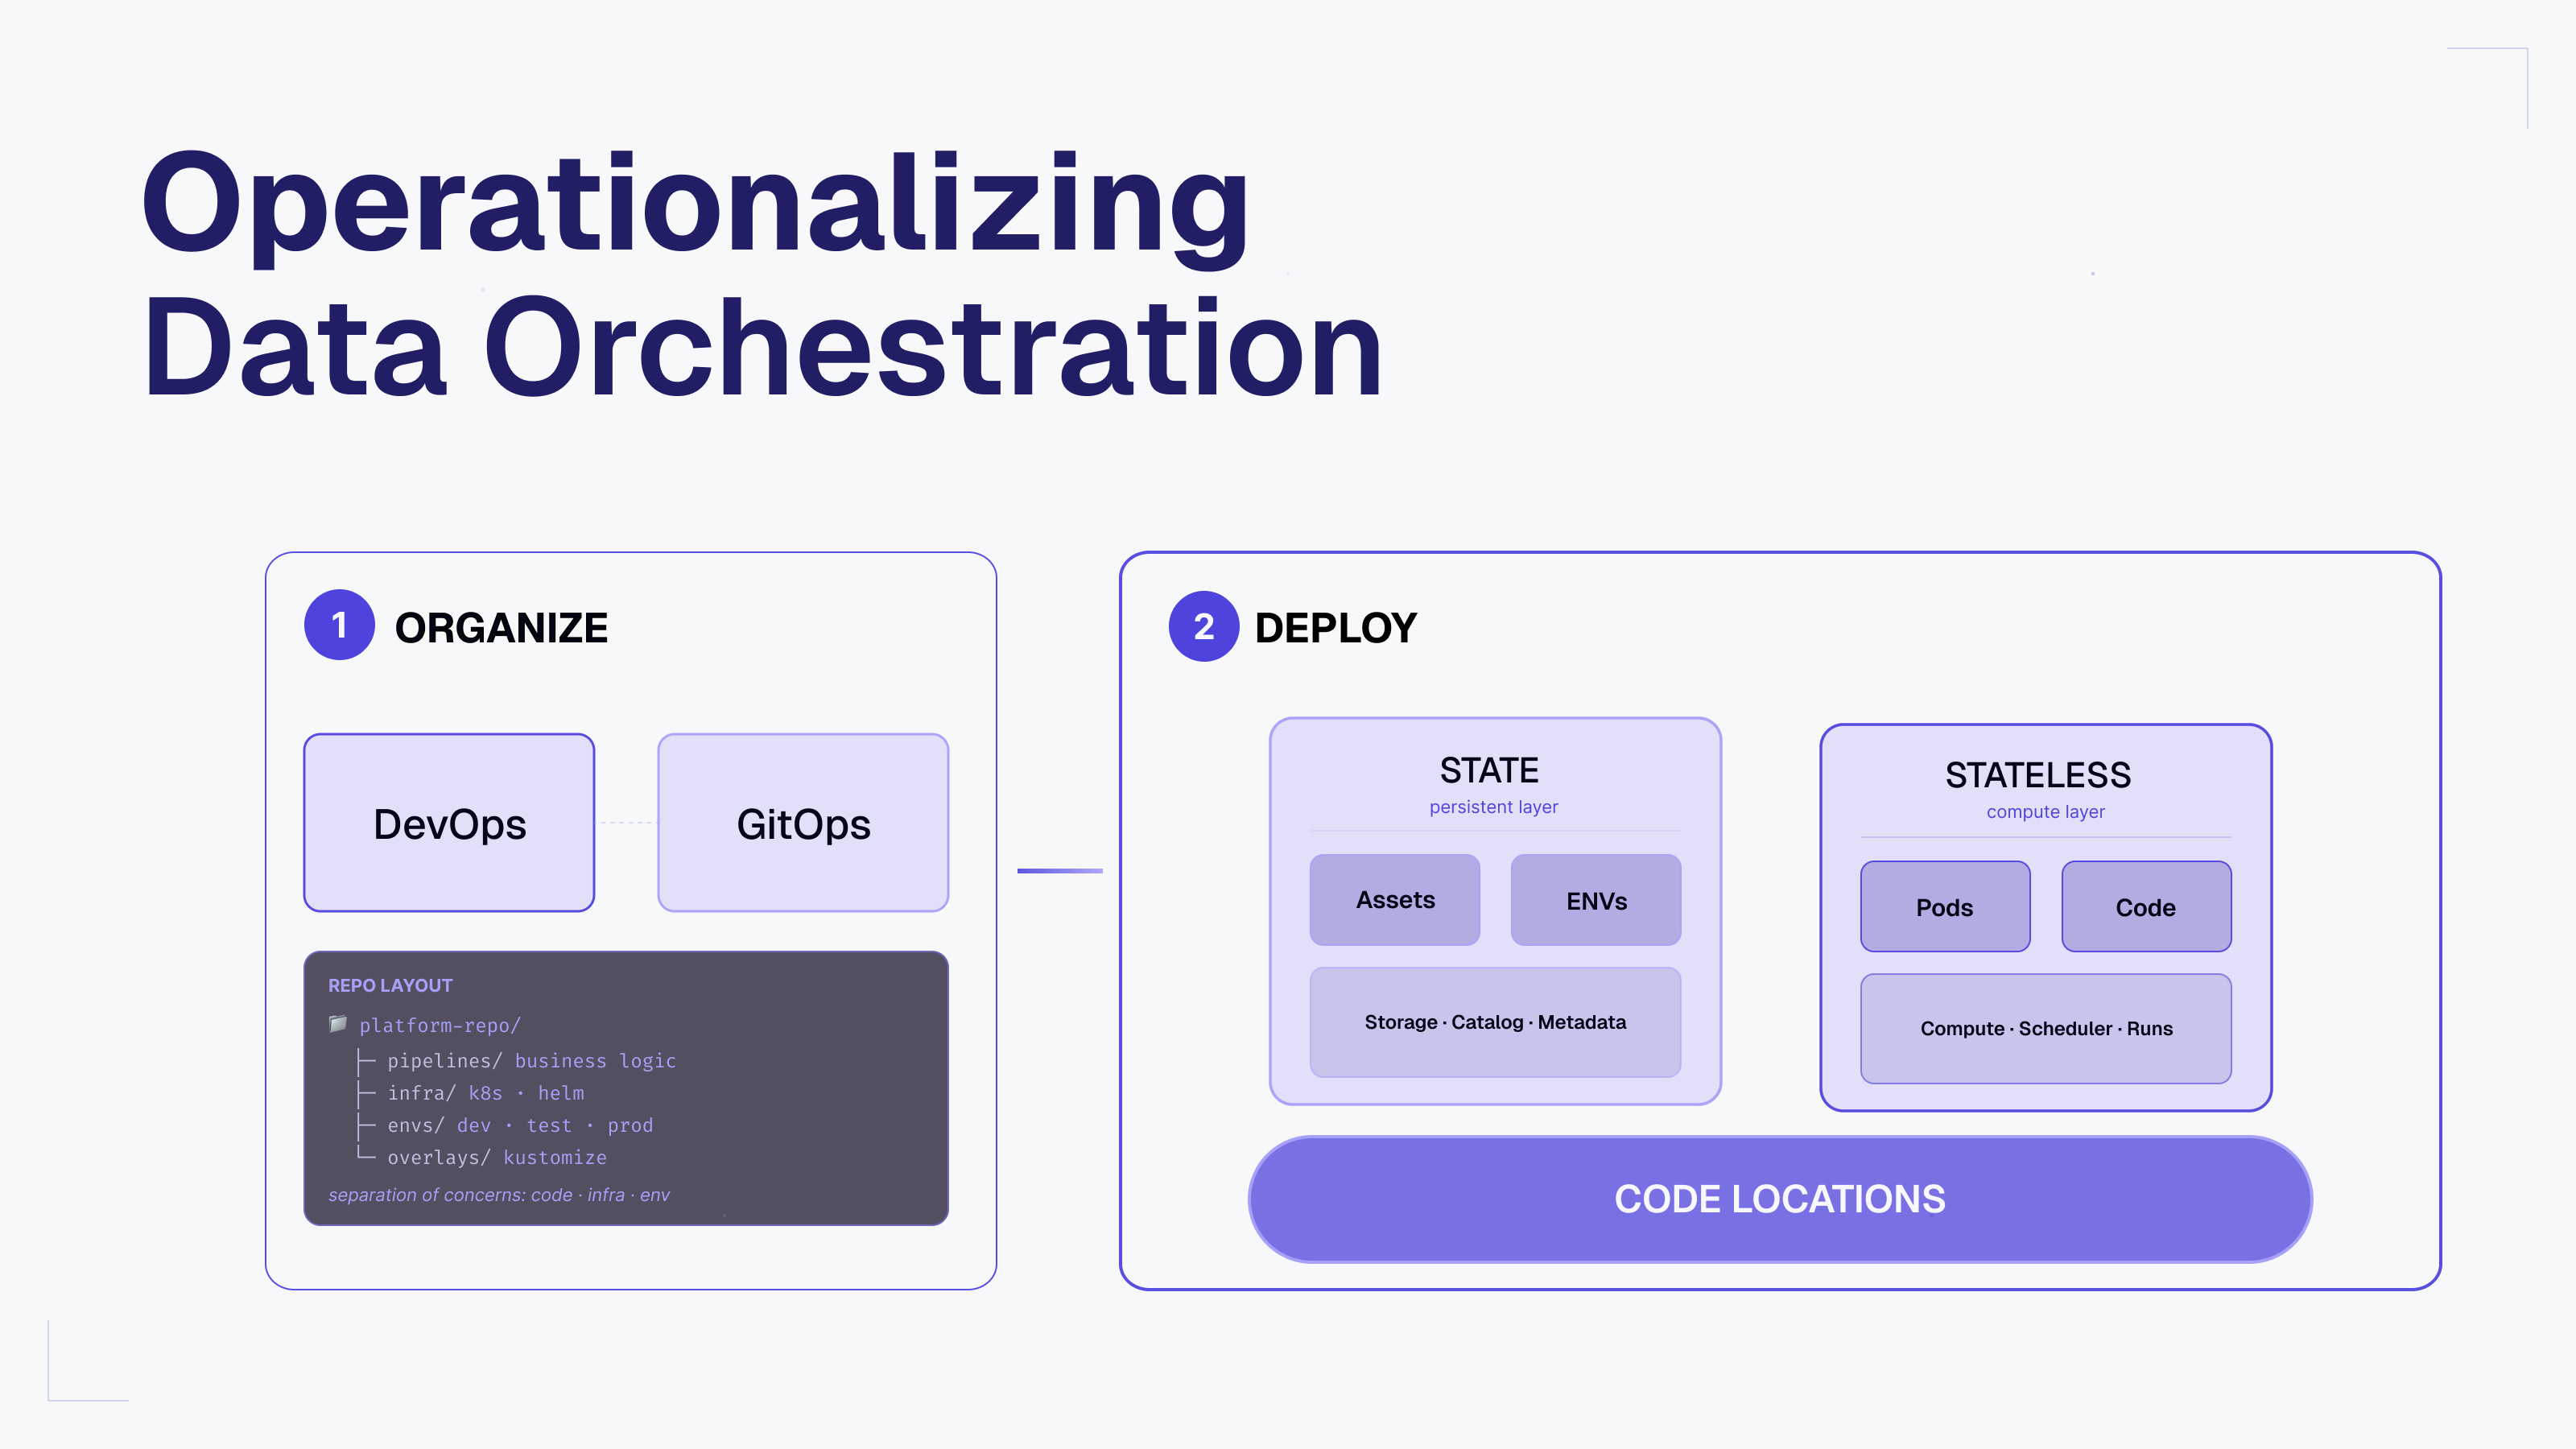
A complete guide with all the insights, tips, and some predictions for the data platform engineer, just like an Almanack provides, with practical information for daily life.
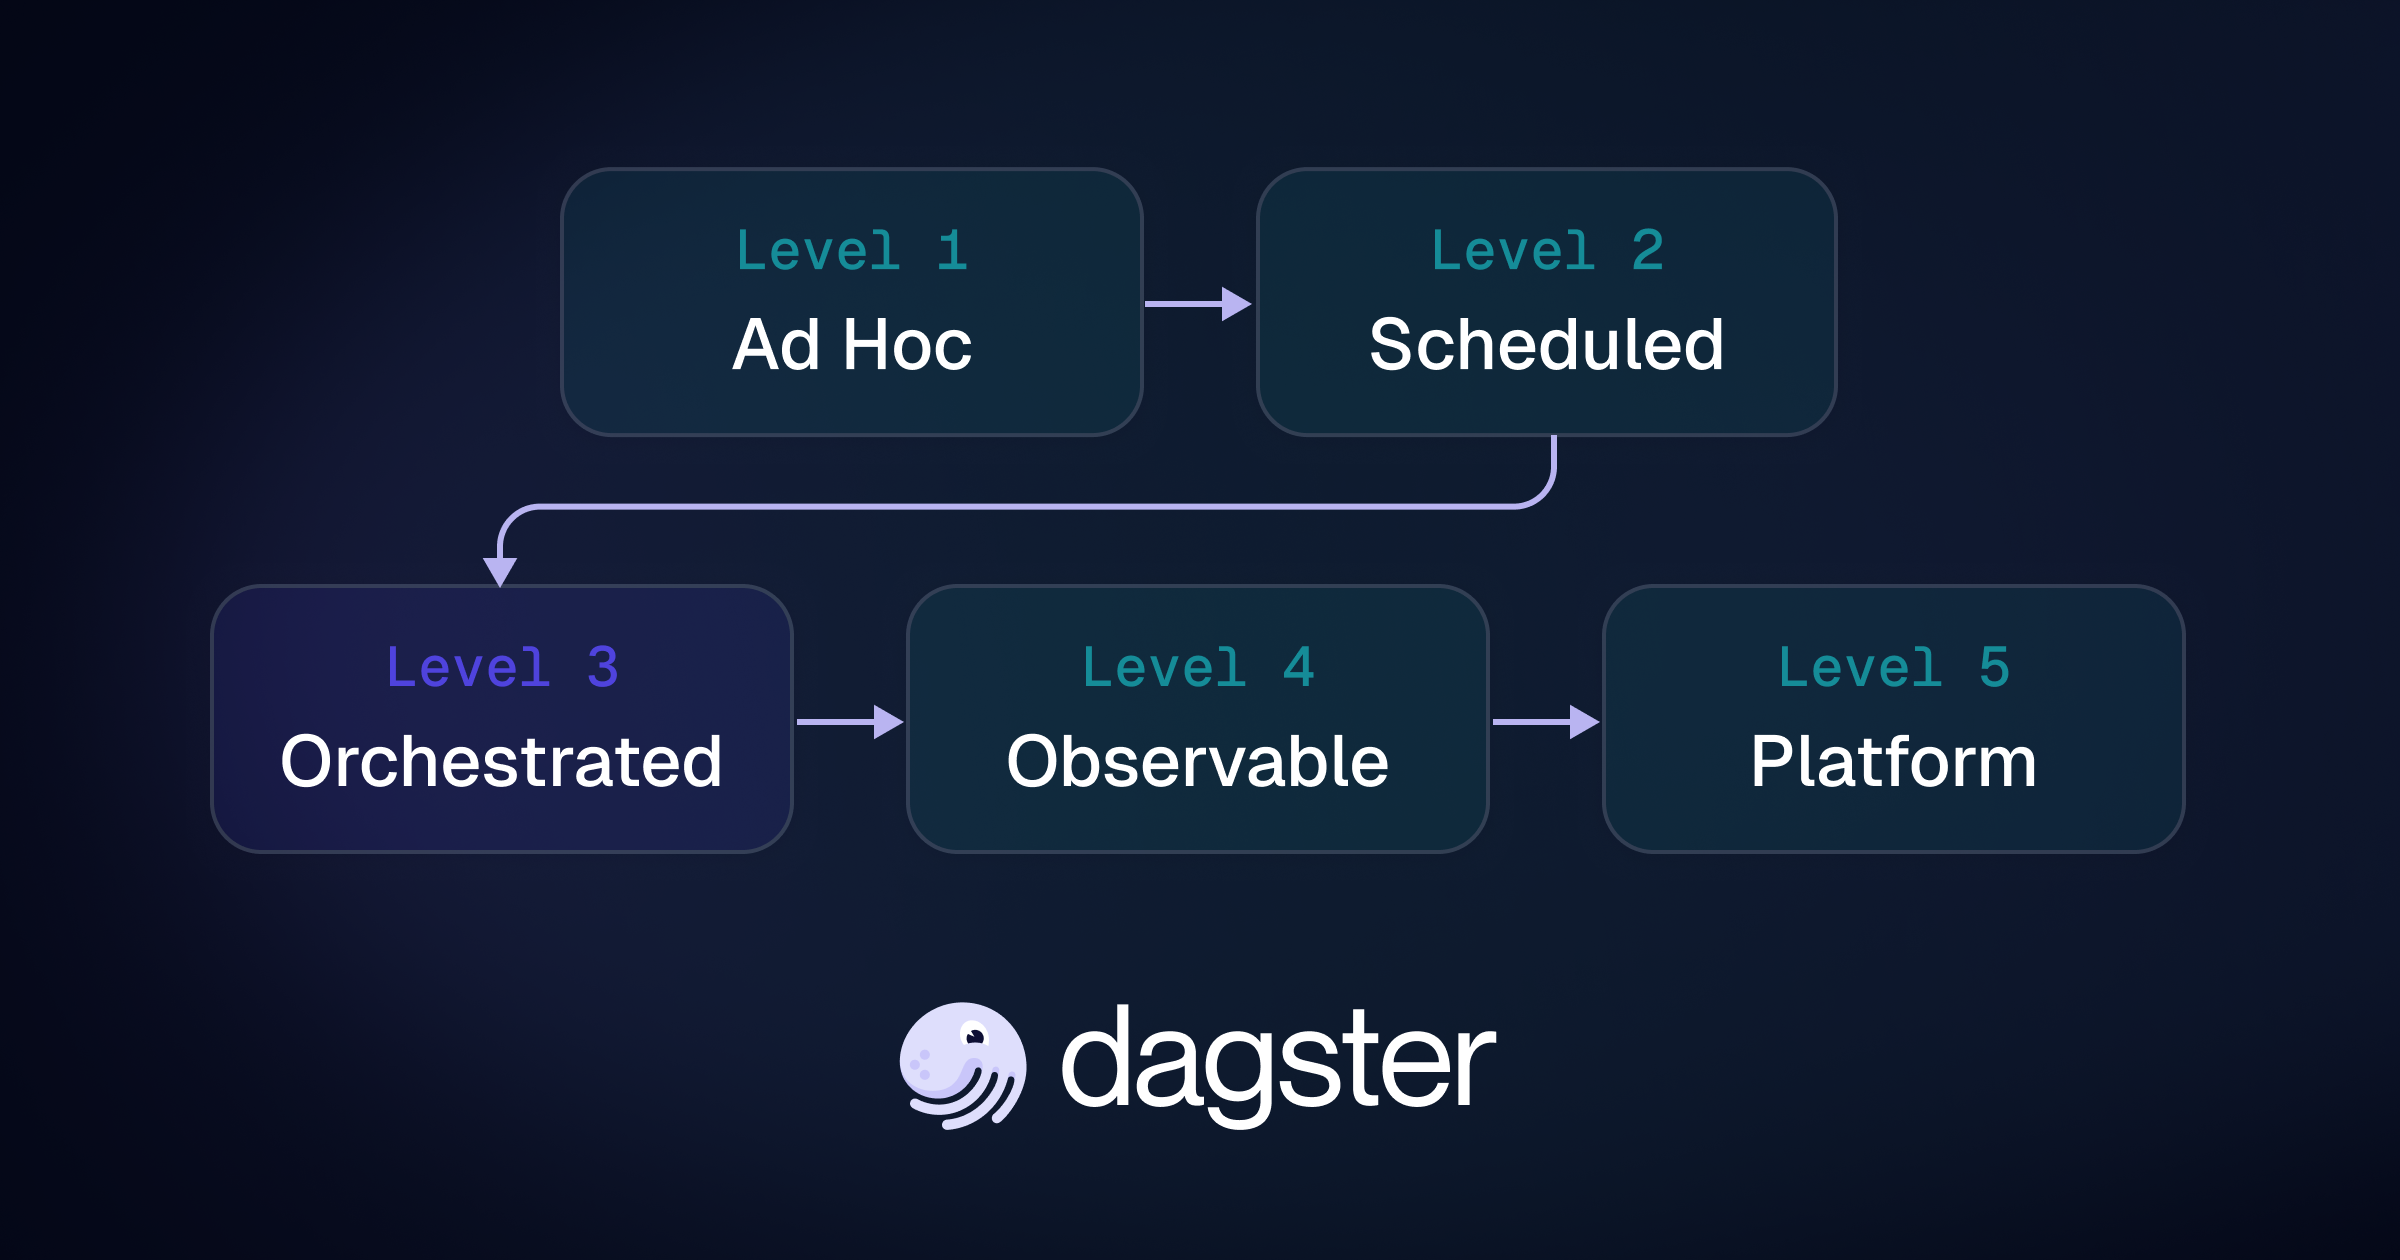
Mature orchestration environments often work operationally while still leaving critical data dependencies implicit. This post introduces the Orchestration Maturity Model, explains the architectural ceiling of job-centric systems, and shows how Dagster’s asset-aware approach helps teams reason about freshness, lineage, quality, and self-service at enterprise scale.
Some of the most interesting Dagster projects come from the community. This post highlights creative community-built applications.
Text-to-analytics promises self-service access to data, but adoption depends on usability, governance, and trust. In this guest post, Brooklyn Data explains how it evaluated Compass, deployed it on top of Snowflake, and enabled teams to answer operational questions directly in Slack while maintaining centralized governance and business context.
Snowflake increasingly handles transformation and data freshness internally through features like Dynamic Tables and Cortex. Dagster complements Snowflake by providing orchestration, lineage, automation, and cost visibility across your broader data platform from SQL-defined assets to downstream automation and Snowflake query attribution.
We adopted Astral’s new Python type checker, ty, to speed up type checking in the Dagster monorepo. The performance gains were dramatic, but the bigger surprise was that ty caught real runtime bugs Pyright missed. Here’s what we learned migrating a large Python codebase incrementally to ty.
A complete guide with all the insights, tips, and some predictions for the data platform engineer, just like an Almanack provides, with practical information for daily life.
The Dagster+ Terraform provider lets platform teams manage deployments, access controls, alerting, and more as code. Define entire environments declaratively, review changes through pull requests, and integrate Dagster+ into your existing infrastructure workflows.
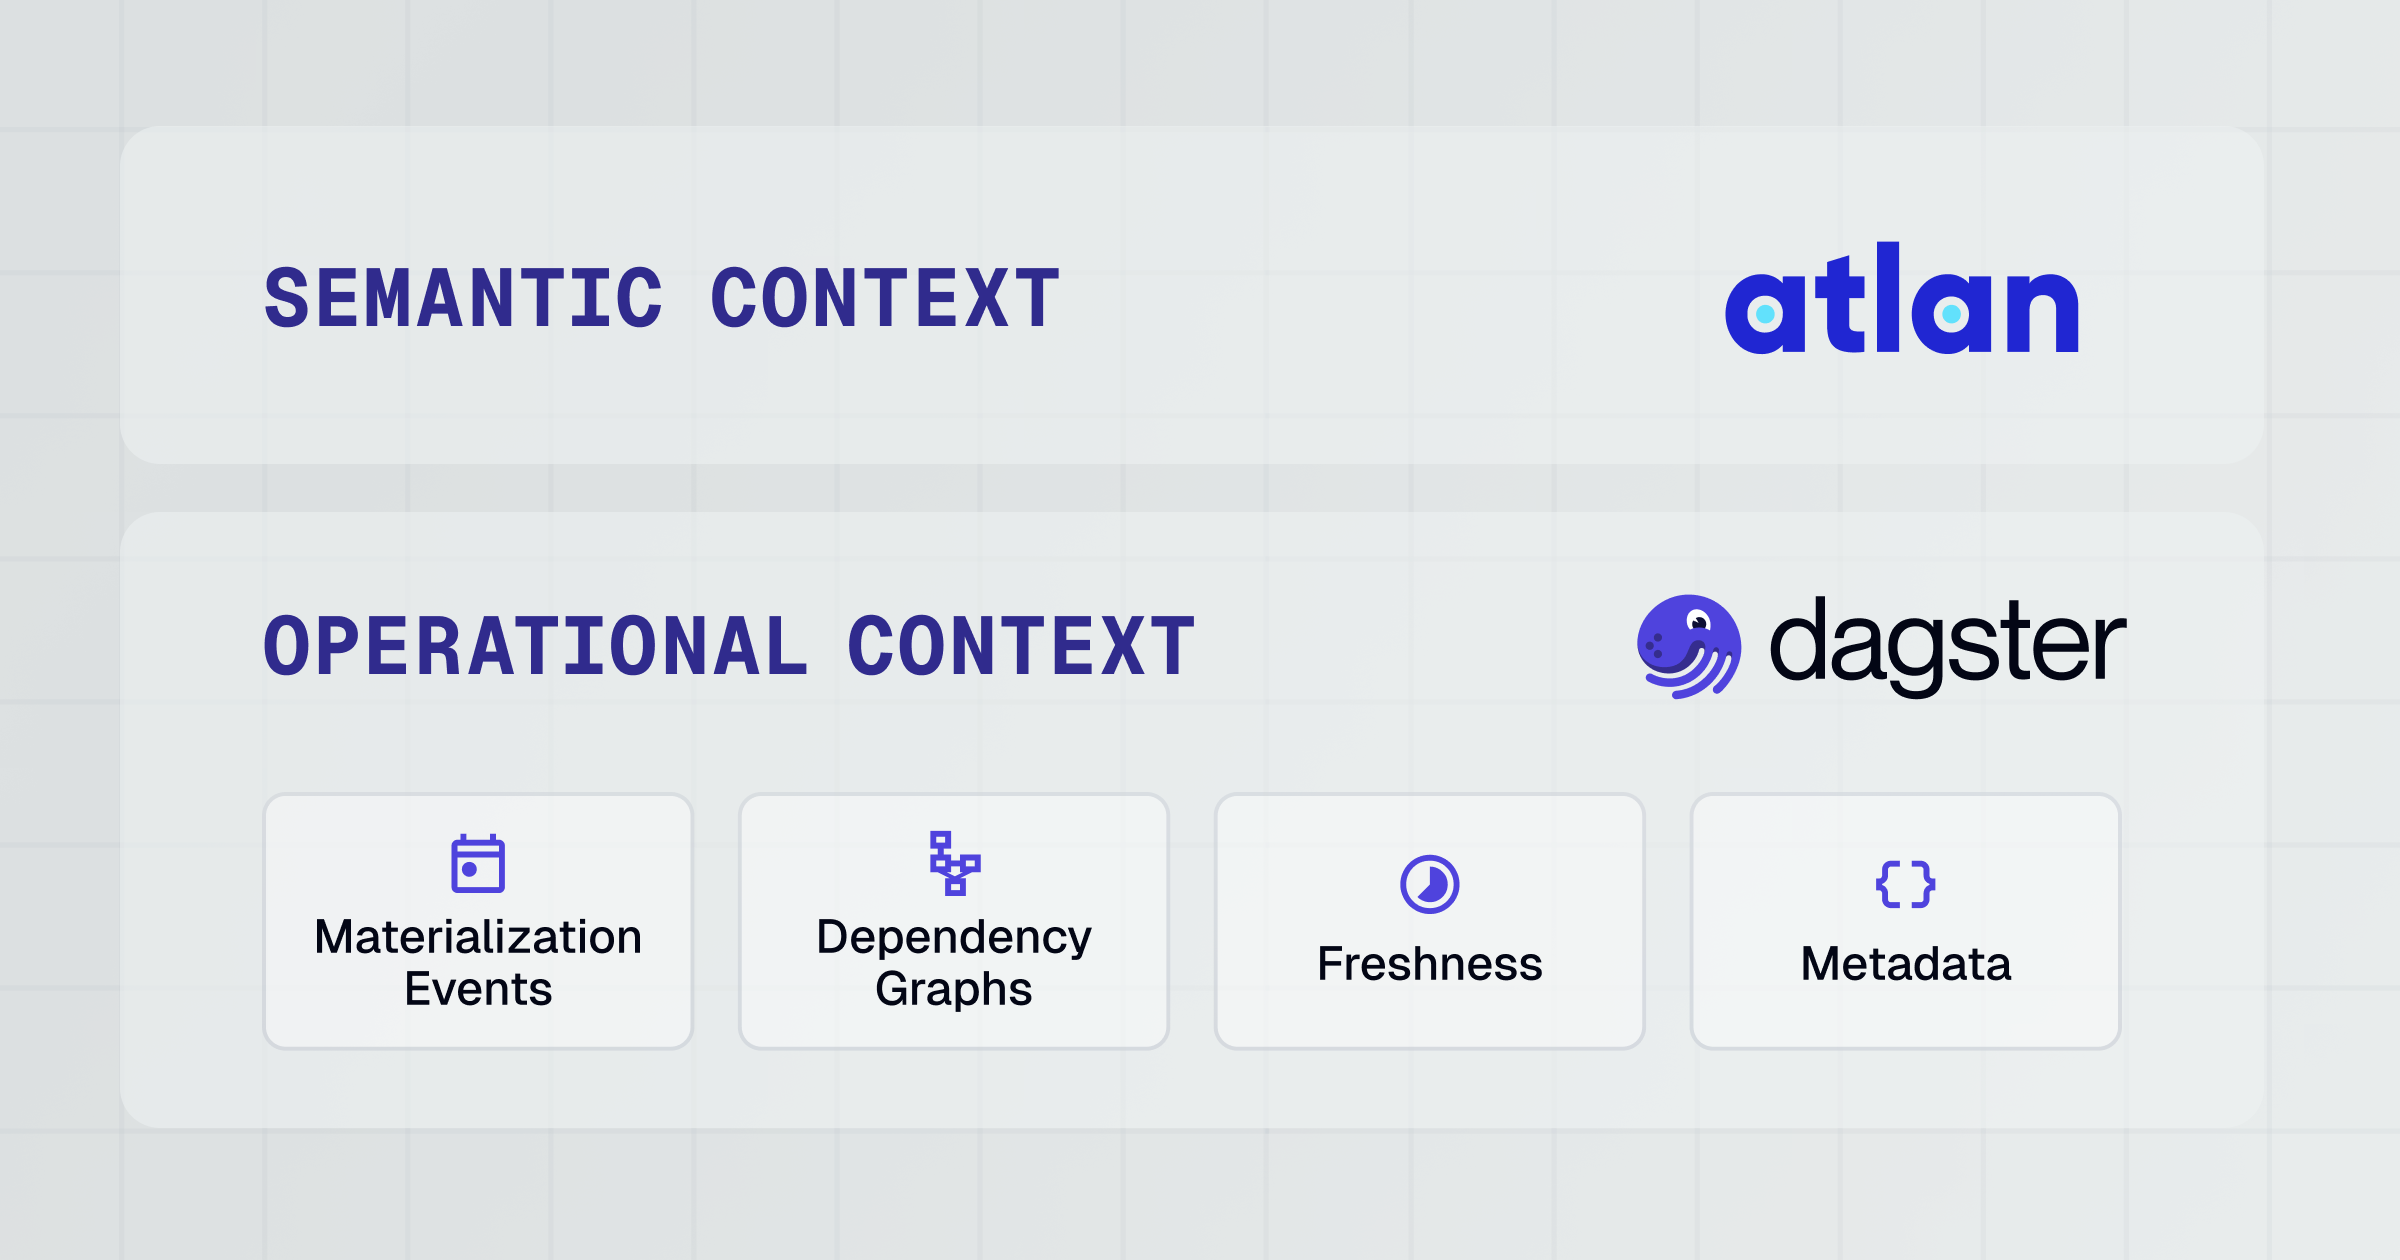
AI agents that only understand business definitions without knowing whether the underlying pipeline actually succeeded are confidently wrong and operational context from the orchestrator is the missing piece.
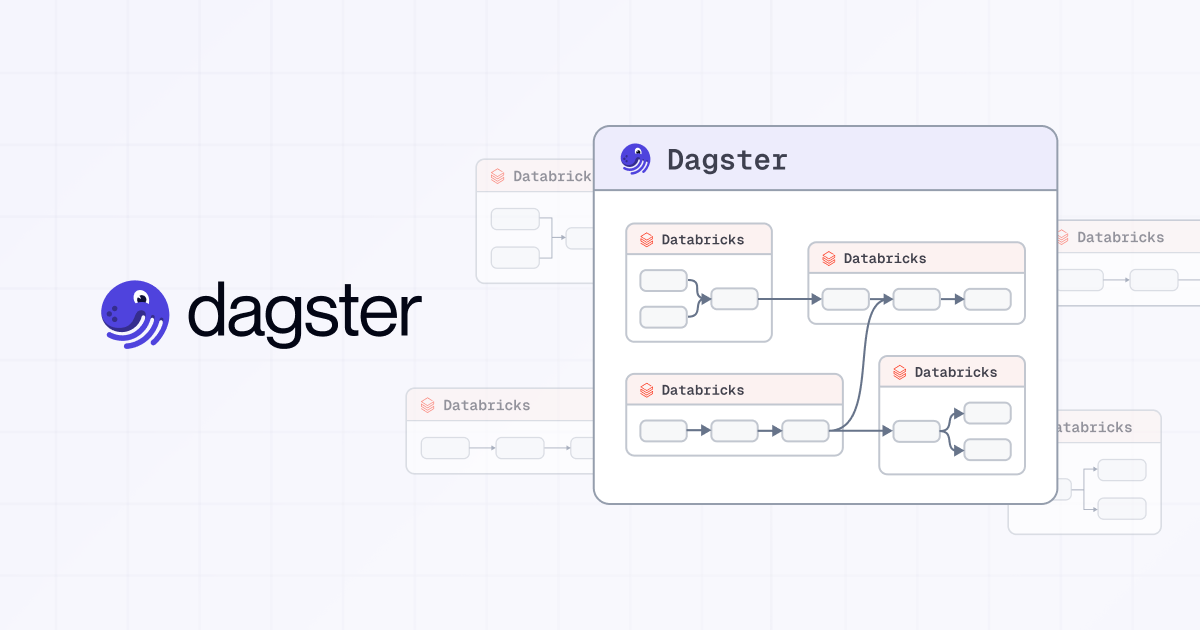
Once your pipelines span multiple Databricks workspaces, you're no longer orchestrating a single system you're coordinating a distributed one.
Dagster skills, partitioned asset checks, state backed components, virtual assets, and stronger integrations.
How we configure Copybara for bi-directional syncing to enable a hub-and-spoke model for Git repositories
AI has made contributing to open source easier but reviewing contributions is still hard. At Dagster, we’re improving the contributor experience with smarter review tooling, clearer guidelines, and a focus on contributions that are easier to evaluate, merge, and maintain.
DataOps is about building a system that provides visibility into what's happening and control over how it behaves
Standardizing on Databricks is a smart strategic move, but consolidation alone does not create a working operating model across teams, tools, and downstream systems. By pairing Databricks and Unity Catalog with Dagster, enterprises can add the coordination layer needed for dependency visibility, end-to-end lineage, and faster, more confident delivery at scale.
AI coding agents are changing how data engineers work. This Dagster University course shows how to build a production-ready ELT pipeline from prompts while learning practical patterns for reliable AI-assisted development.
Dagster OSS is built for builders. But as teams grow, the operational burden of running the platform can quietly consume engineering time. This guide explains when it makes sense to move to Dagster+ and shift your focus back to building data products.
Learn how Metaxy can be used to build multimodal data pipelines with sample-level granularity on Dagster
We built a light weight evaluation framework to quantiatively measure the effectiveness of the Dagster Skills, and these are our findings.
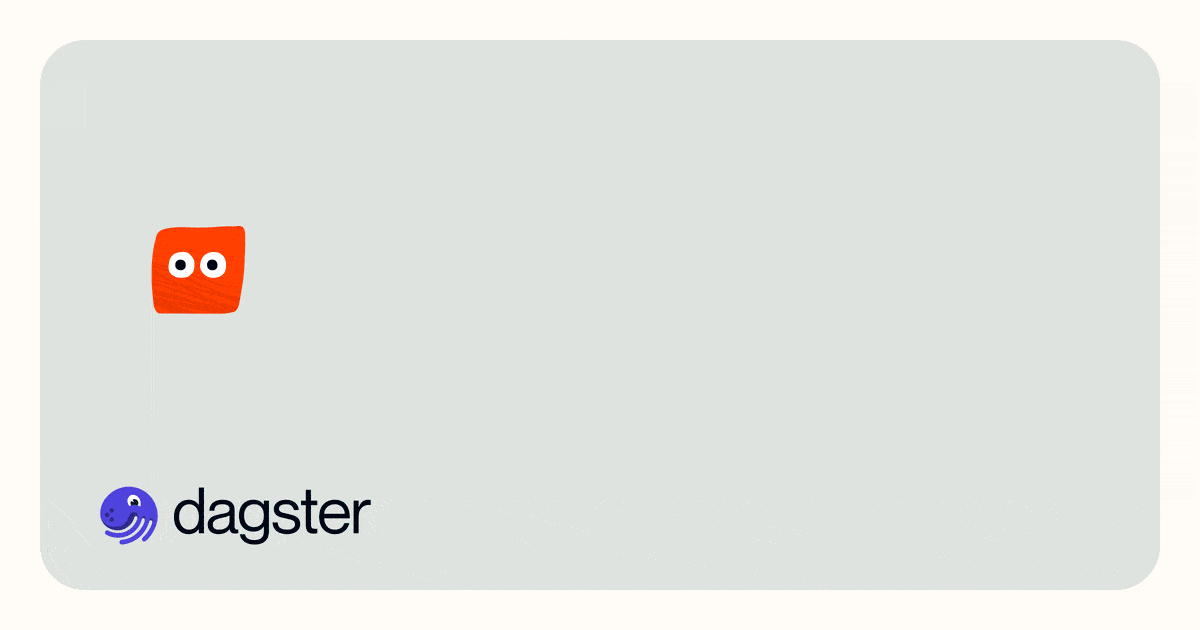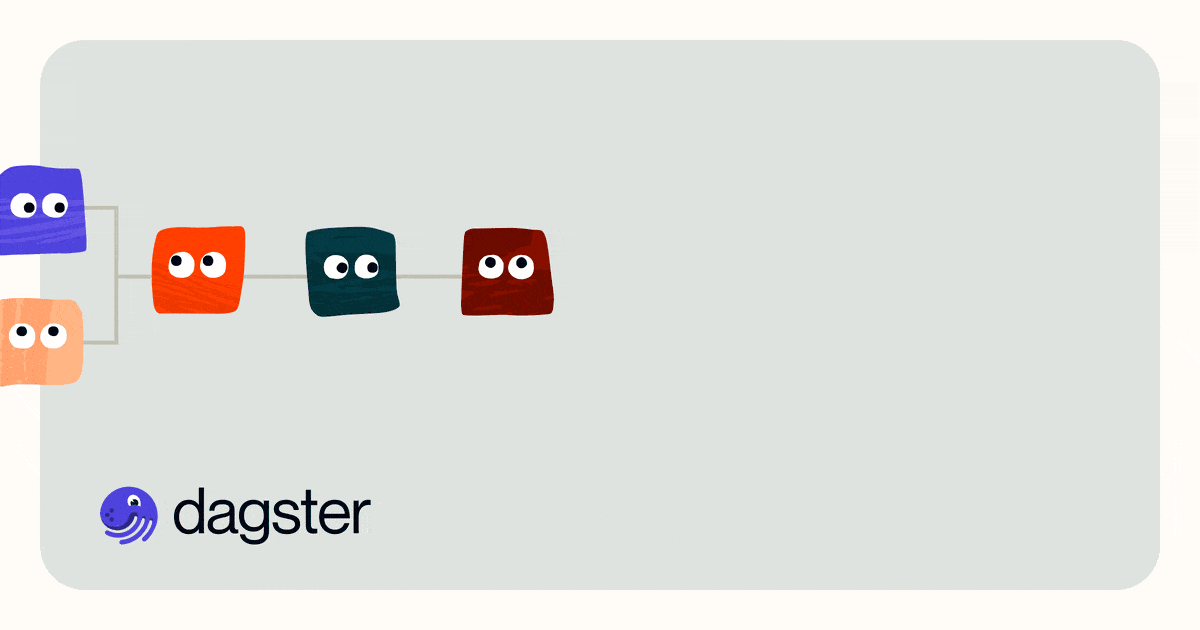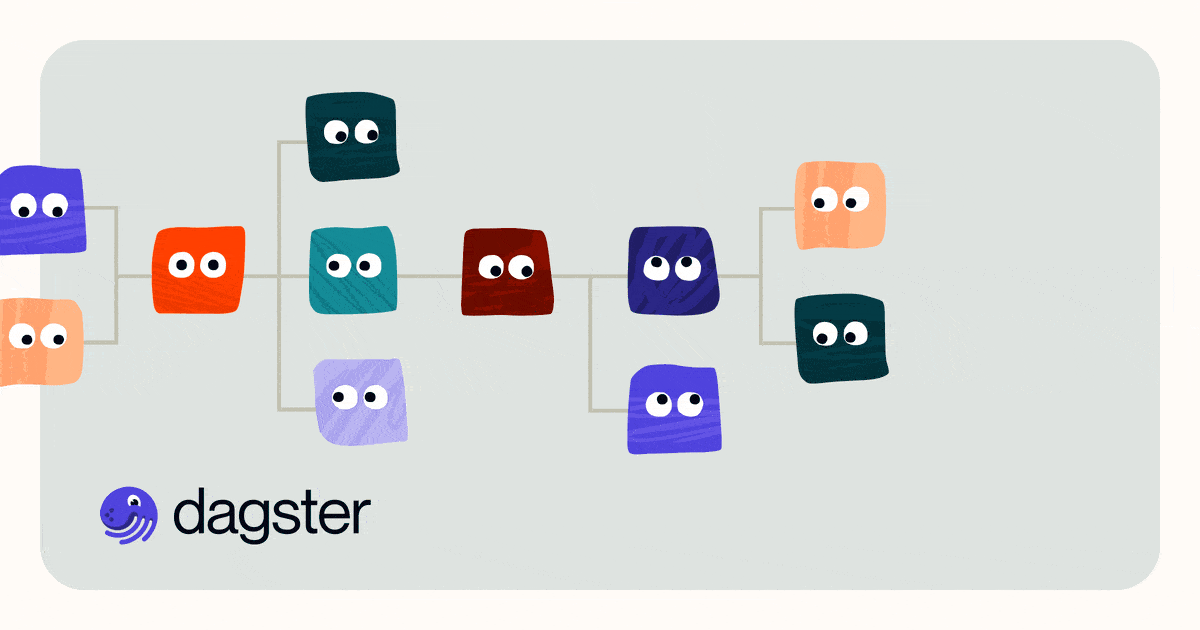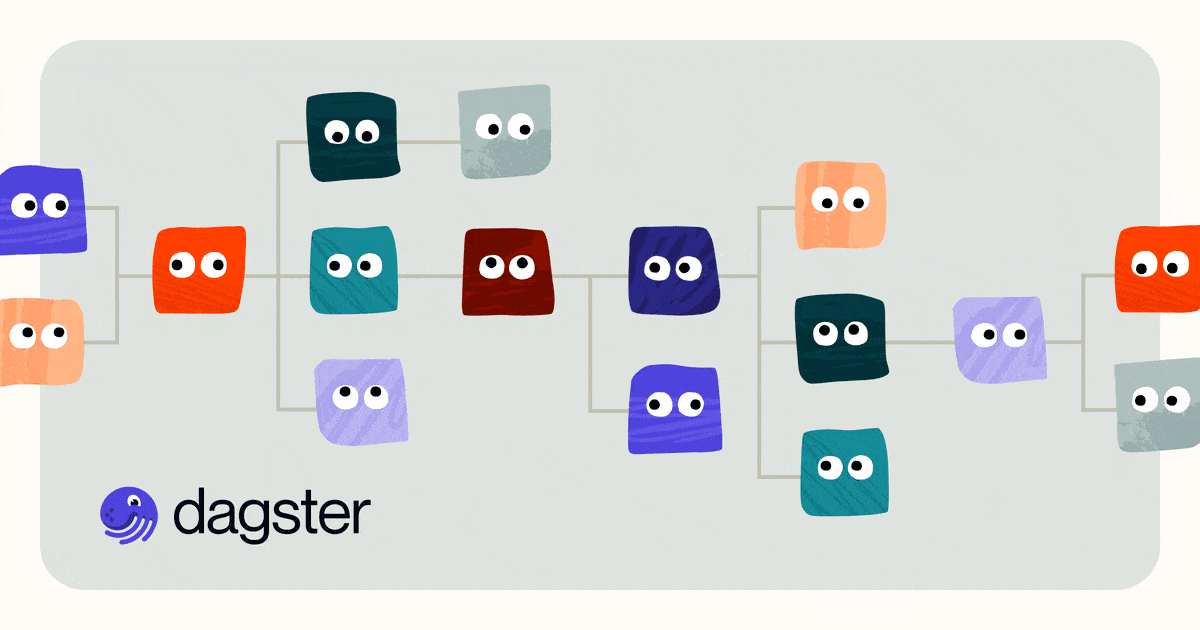
We set out to explain Dagster assets in the simplest possible way: as living characters that wait, react, and change with their dependencies. By designing a children’s book with warmth, visuals, and motion, we rediscovered what makes assets compelling in the first place.
Detection isn't the bottleneck anymore. Understanding is. Compass closes the loop by turning Dagster+ operational data into a conversation.
When agents write tests, intent matters as much as correctness. By defining clear testing levels, preferred patterns, and explicit anti-patterns, we give agents the structure they need to produce fast, reliable Pytest suites that scale with automation.
Snowflake handles AI compute while Dagster handles orchestration, observability, and the operational patterns that turn AI experiments into reliable production pipelines.
Compass now connects directly to your go-to-market tools, letting you ask questions about pipeline, ad spend, and sales conversations in Slack without exporting CSVs or waiting on the data team.
Modern LLMs generate patterns, not principles. Dignified Python gives agents the intent they lack, ensuring code is explicit, consistent, and engineered with care. Here are ten rules from our Claude prompt.
Benchmarks measure outcomes, not behavior. By letting AI models play chess in repeatable tournaments, we can observe how they handle risk, repetition, and long-term objectives, revealing patterns that static evals hide.
This post gives you a framework for enforcing data quality at every stage so you catch issues early, maintain trust, and build platforms that actually work in production.
This post introduces a custom async executor for Dagster that enables high-concurrency fan-out, async-native libraries, and incremental adoption, without changing how runs are launched or monitored.
Most teams build data platforms reactively when you should be architecting one that scales with your business, not against it.
Once the model is trained, the final step is getting it into users’ hands. This guide walks through turning your model into a fast, reliable RunPod endpoint—complete with orchestration and automated updates from Dagster.
A practical guide to choosing between push, pull, and poll data ingestion patterns. With real Dagster code examples to help you build reliable, maintainable pipelines.
Automatically sync asset materialization events and lineage from Dagster Cloud to Atlan
Training an LLM isn’t one job—it’s a sequence of carefully managed stages. This part shows how Dagster coordinates your training steps on RunPod so every experiment is reproducible, scalable, and GPU-efficient.
Every great model starts with great data. This first part walks through how to structure ingestion with Dagster, prepare your text corpus, and build a tokenizer that shapes how your model understands the world.
Engineers often optimize the wrong parts of their pipelines, here's a profiling-first framework to identify real bottlenecks and avoid the premature optimization trap.
Compass now supports every major data warehouse. Connect your own data and get AI-powered answers directly in Slack, with your governance intact and your data staying exactly where it is.
Learn how real data teams, from solo practitioners to enterprise-scale organizations, build in Dagster’s new eBook, Scaling Data Teams.
A refined Dagster experience. Faster navigation, GA Components, plug-and-play deployment, improved orchestration with FreshnessPolicies, and a new Support Center for builders at scale.
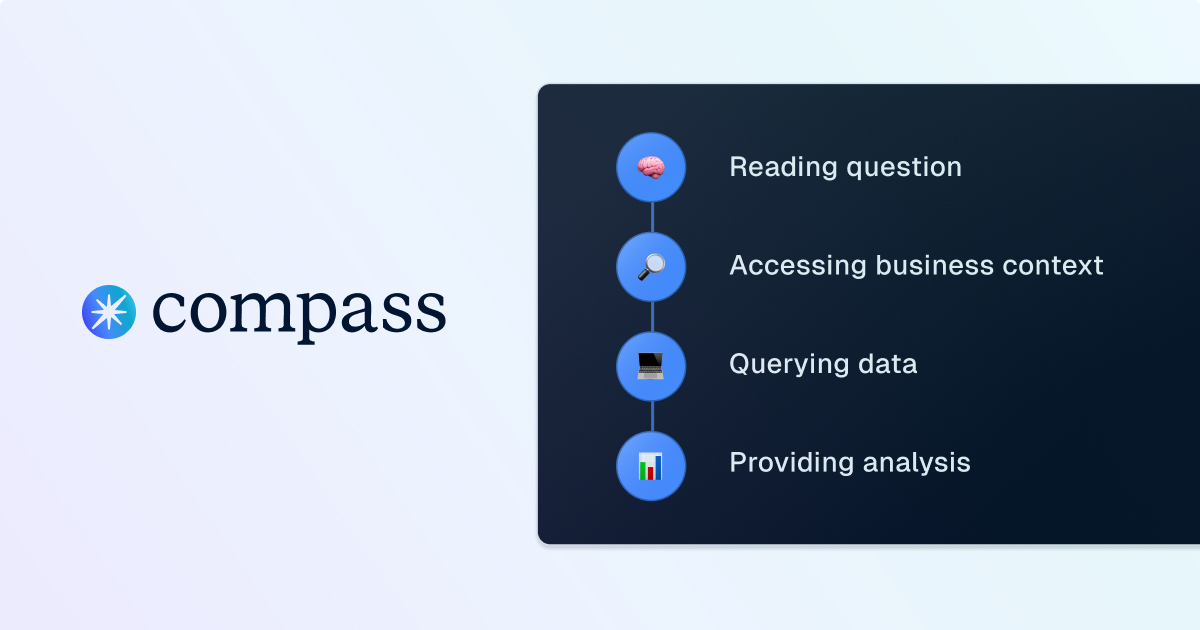
Go behind the scenes of Compass, Dagster’s analyst copilot, to see how it transforms plain-language questions into precise, optimized SQL queries. Learn how each step of the query-generation process helps analysts move faster and stay focused on insights.
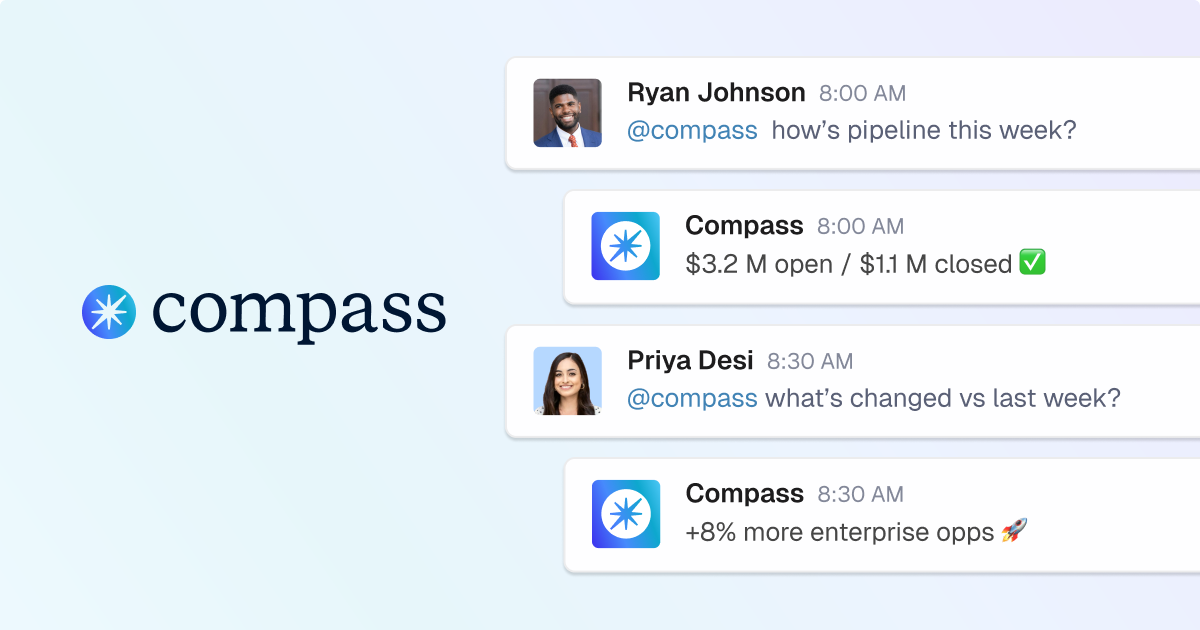
Learn how to maximize the impact of your data stack with a lean team—keeping your analysts at the heart of every decision.
Empowering engineers with flexibility and analysts with accessibility
How I took an excellent lakehouse tutorial and made it even better with modern data orchestration
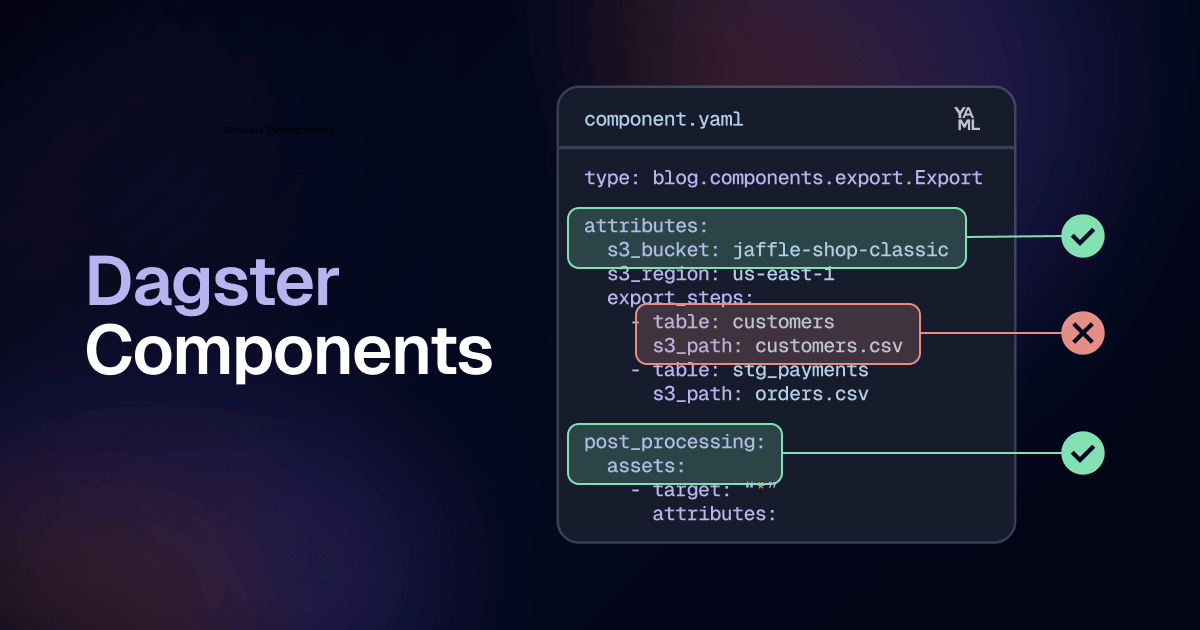
The difference between components that thrive and components that collect digital dust? User experience design.
Featuring YAML-based pipeline definitions, plug-and-play integrations, automatic documentation, and a unified CLI experience.
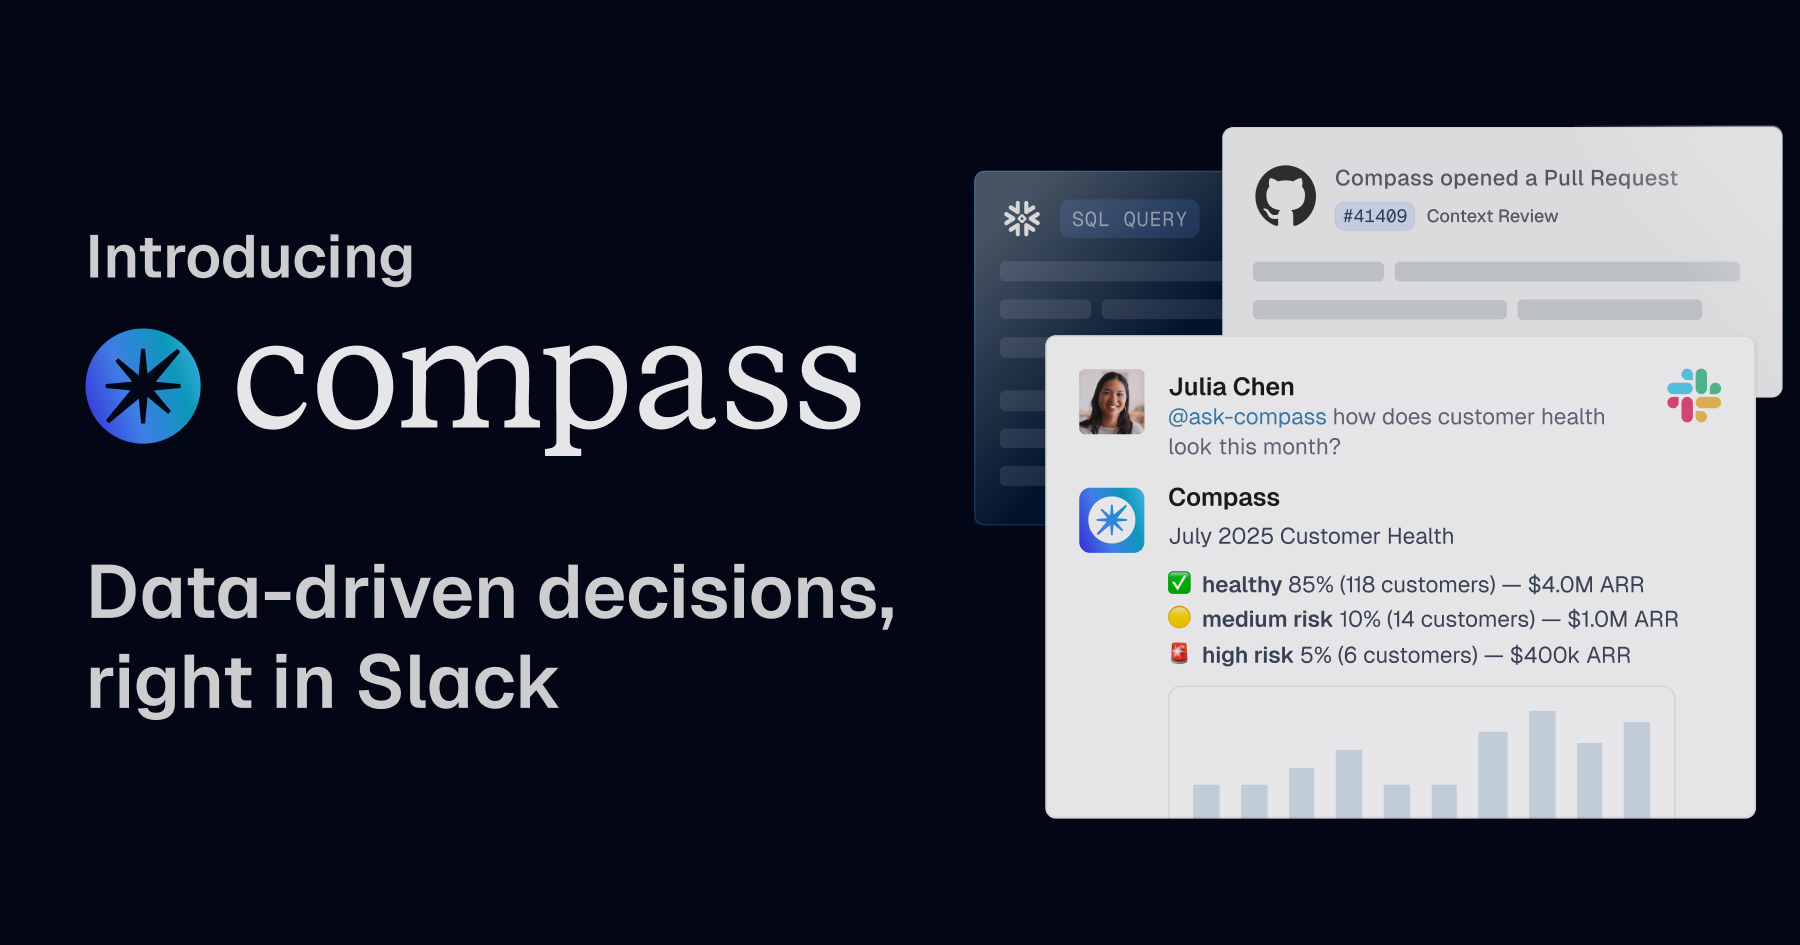
Converse with your company's data right in Dagster. Compass moves beyond static dashboards by enabling a natural language, two-way conversation with your data. This allows anyone to ask follow-up questions, incorporate their own business context, and achieve true data fluency without writing a single line of SQL.
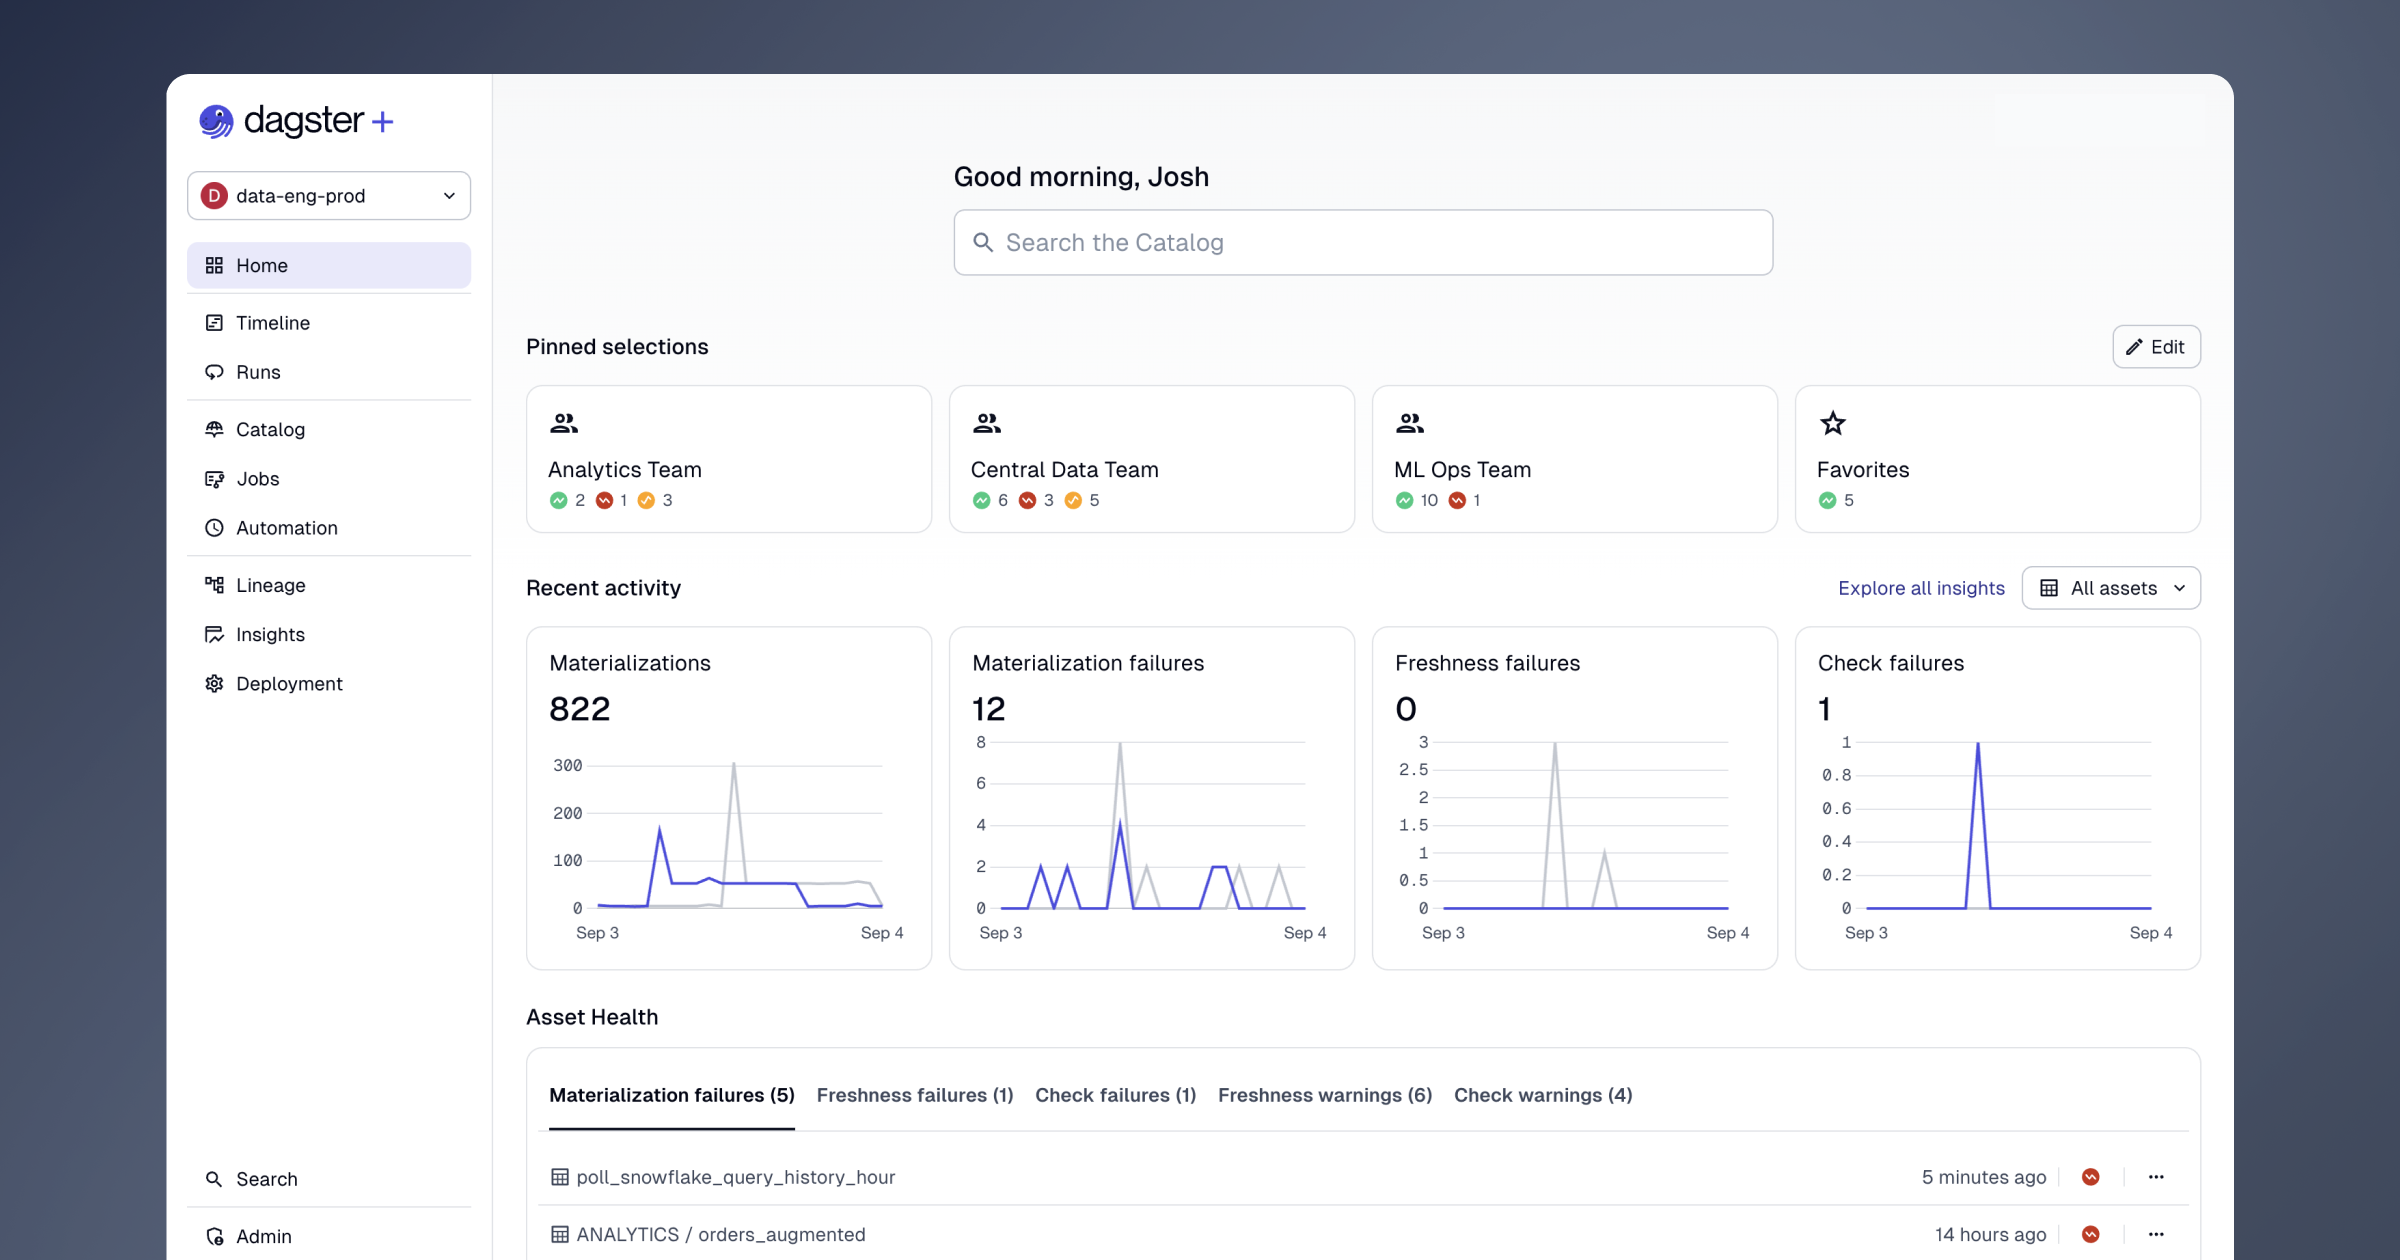
Featuring a new modern homepage, enhanced asset health and freshness monitoring, customizable dashboards, and real-time insights with cost monitoring.
Learn how to use the beta dbt Fusion engine in your Dagster pipelines, and the technical details of how support was added
Explore another set of powerful yet overlooked Python features—from overload and cached_property to contextvars and ExitStack
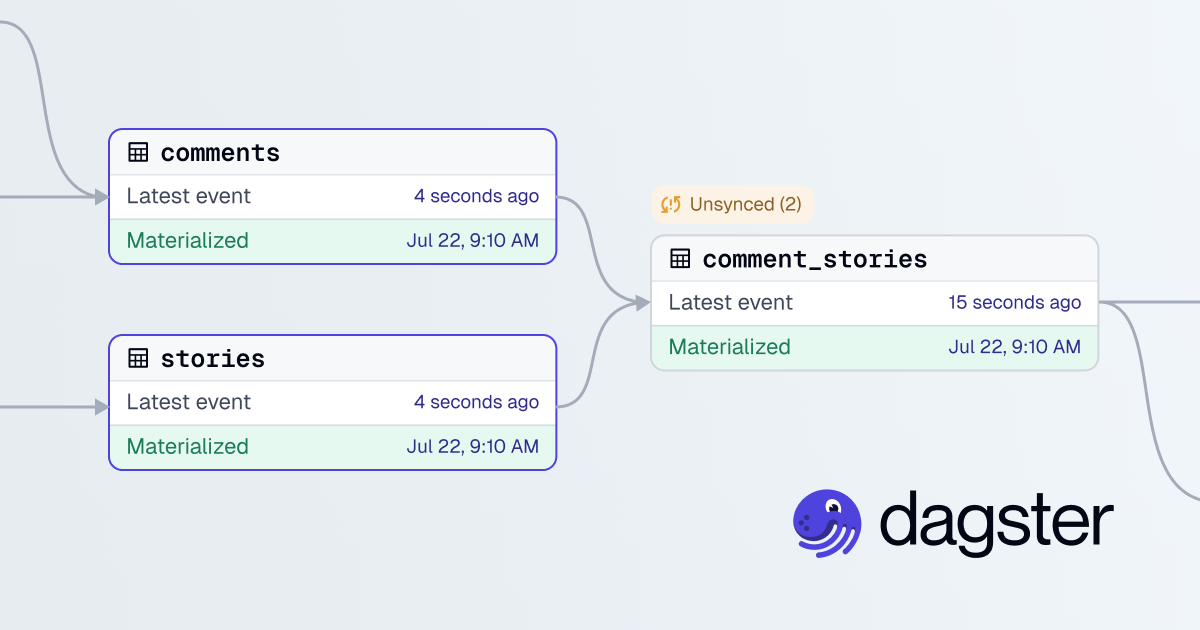
Software-Defined Assets are a new abstraction that allows data teams to focus on the end products, not just the individual tasks, in their data pipeline.
A deep dive into how Dagster leverages pyproject.toml for modern Python packaging, from project metadata and dependencies to build systems and development tooling.
Python's clean syntax makes it easy to jump into unfamiliar codebases, but this simplicity often masks the intricate world of packaging that confuses many developers.
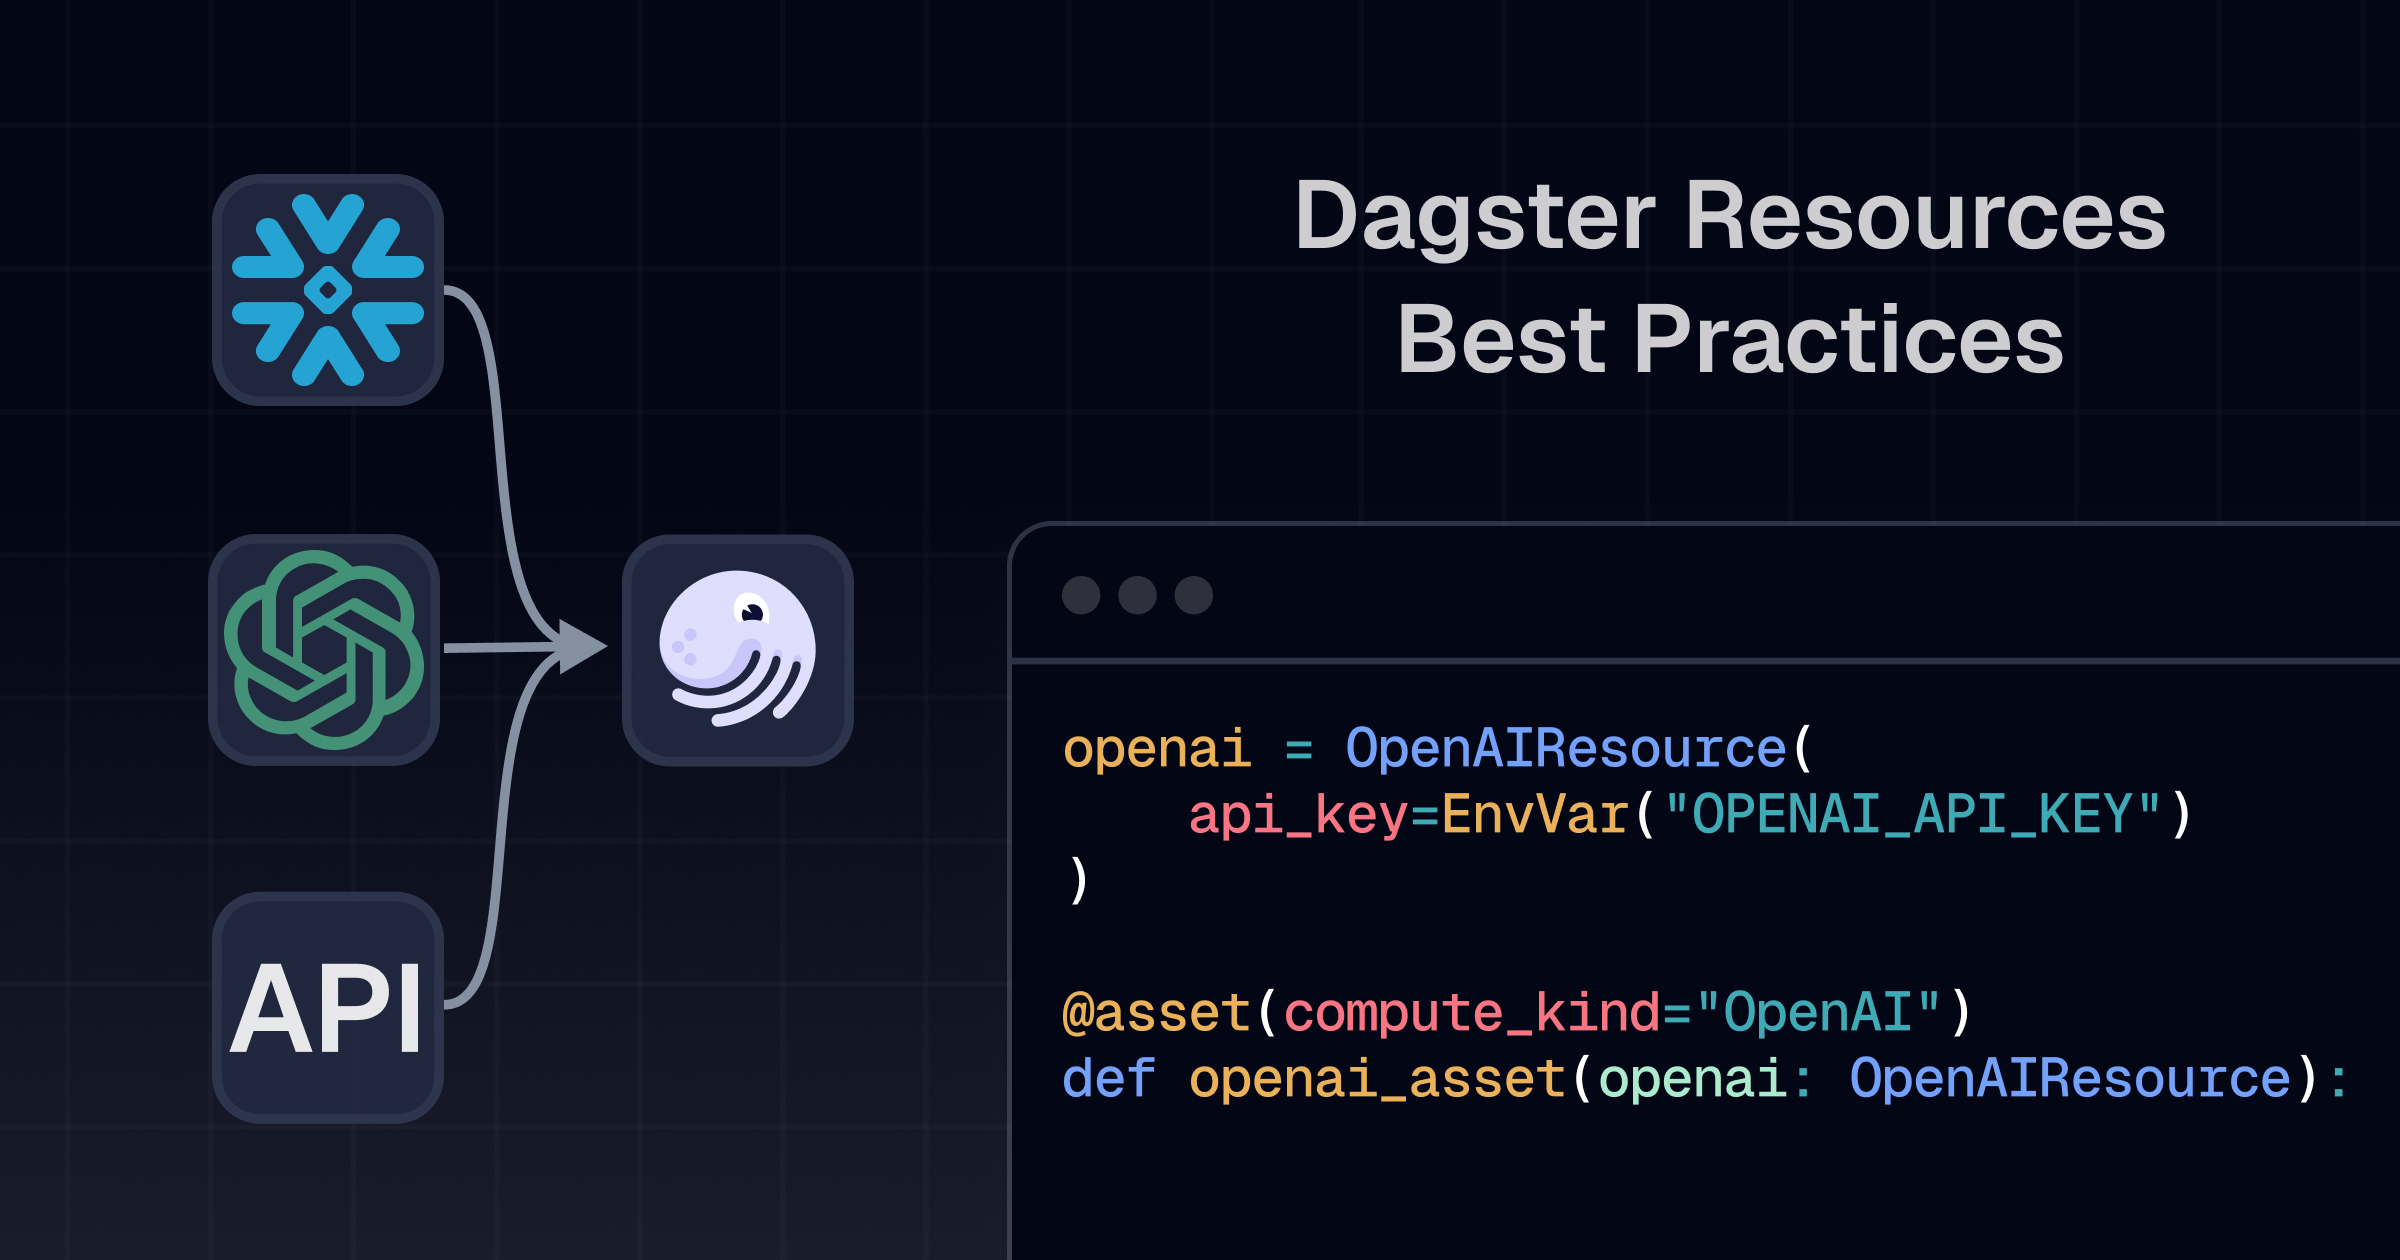
How dependency injection and smart resource management can save your sanity (and your deployments)
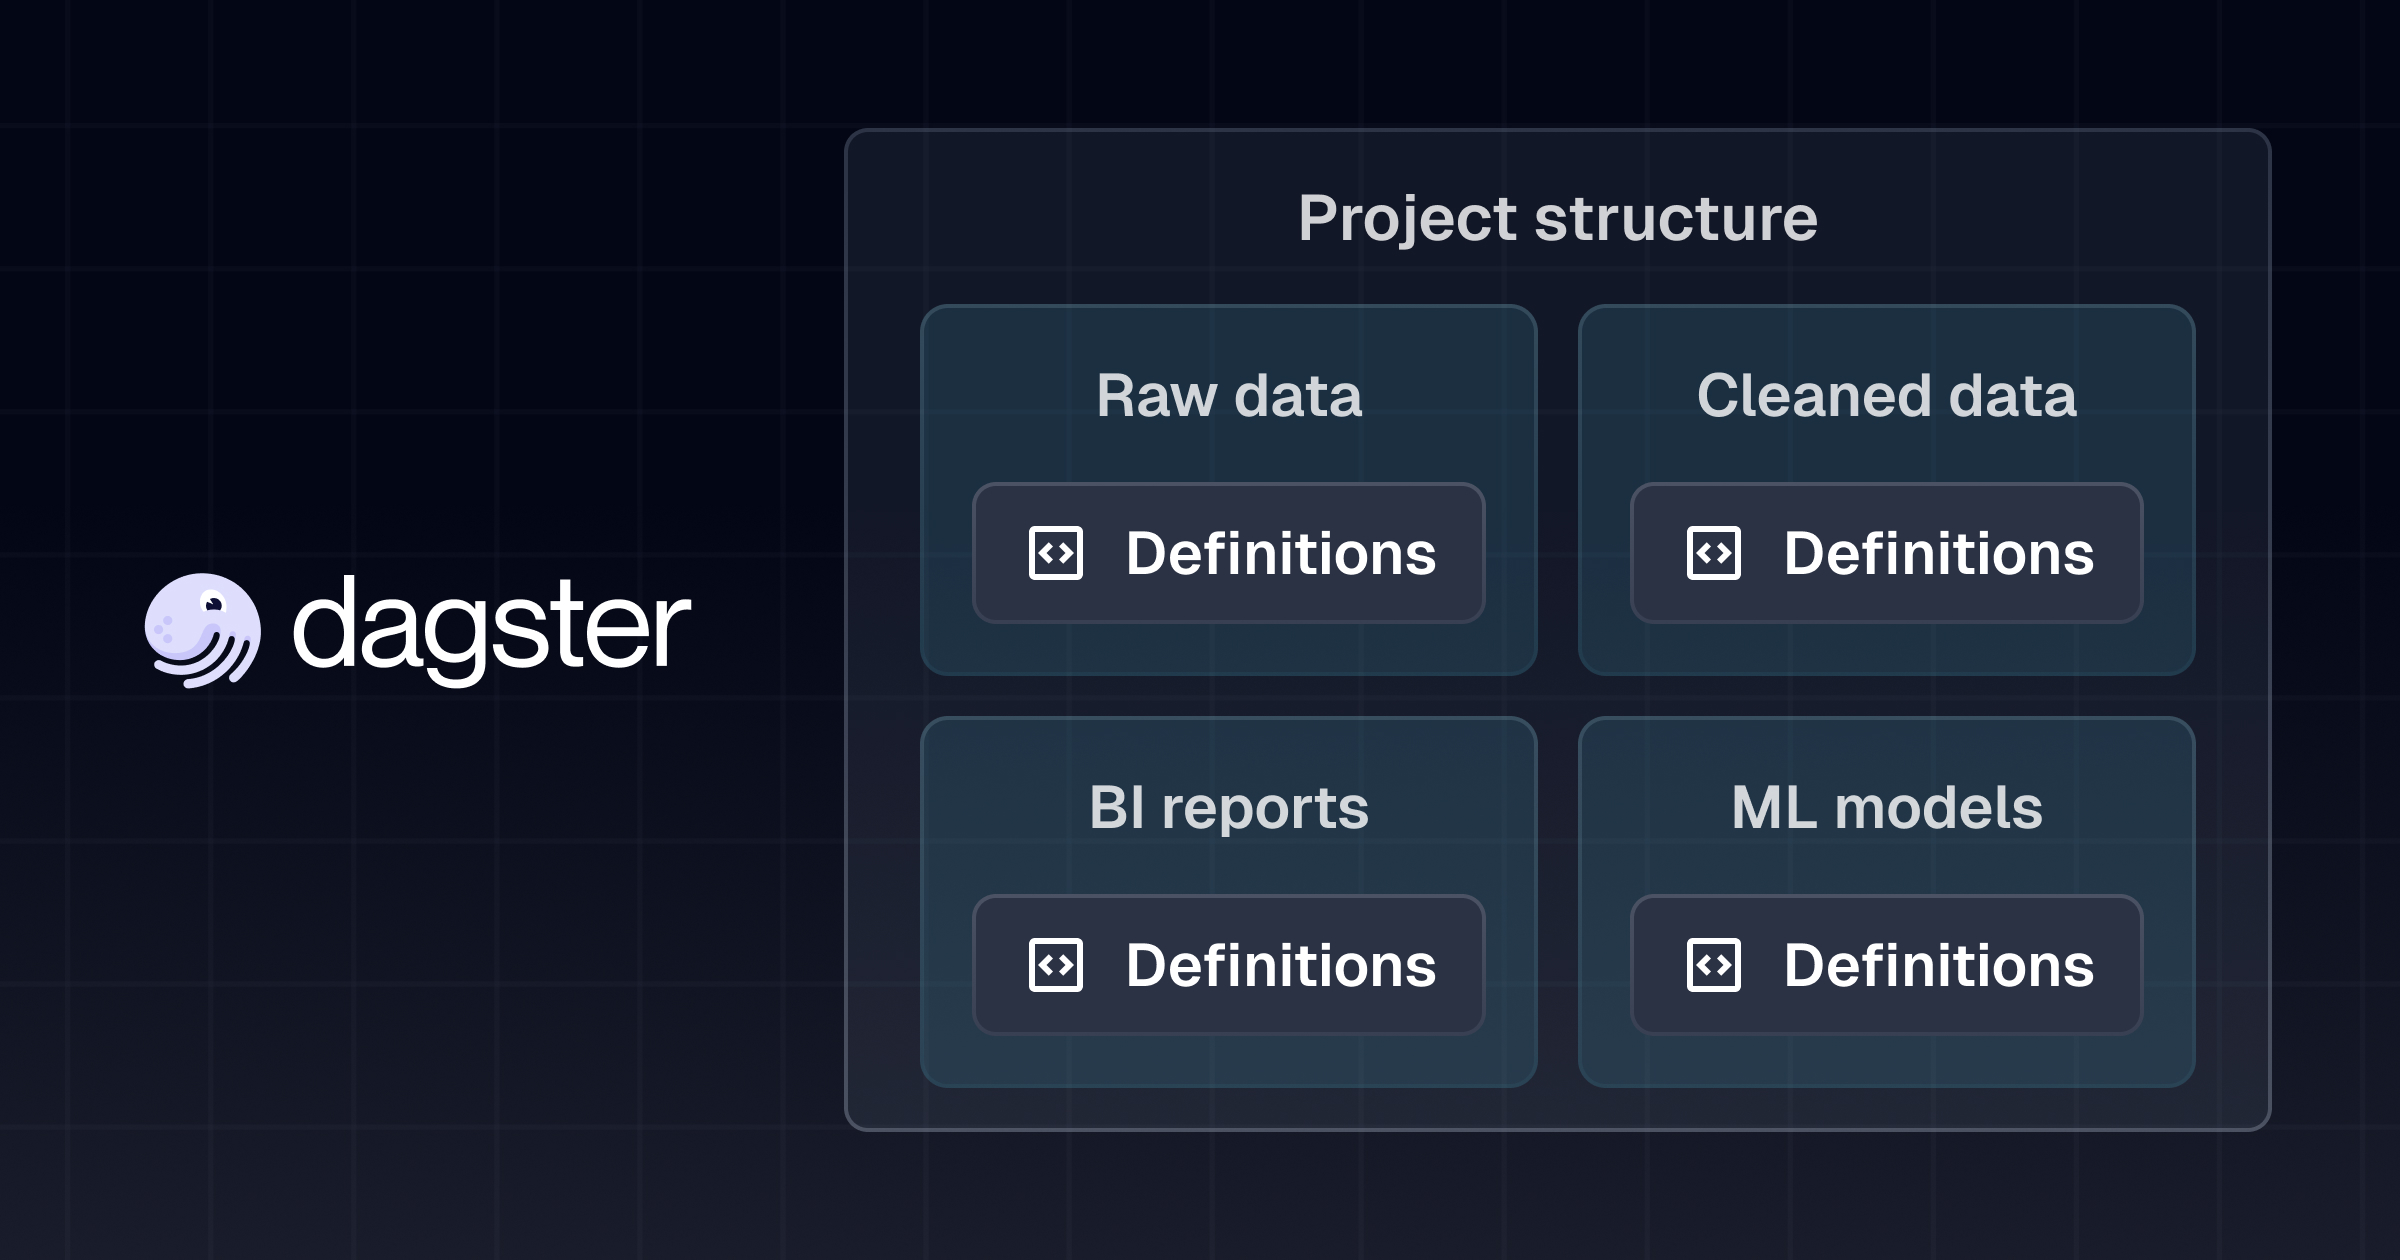
Setting up your Dagster project the right way from day one saves you headaches later, makes your team more effective, and helps scale.
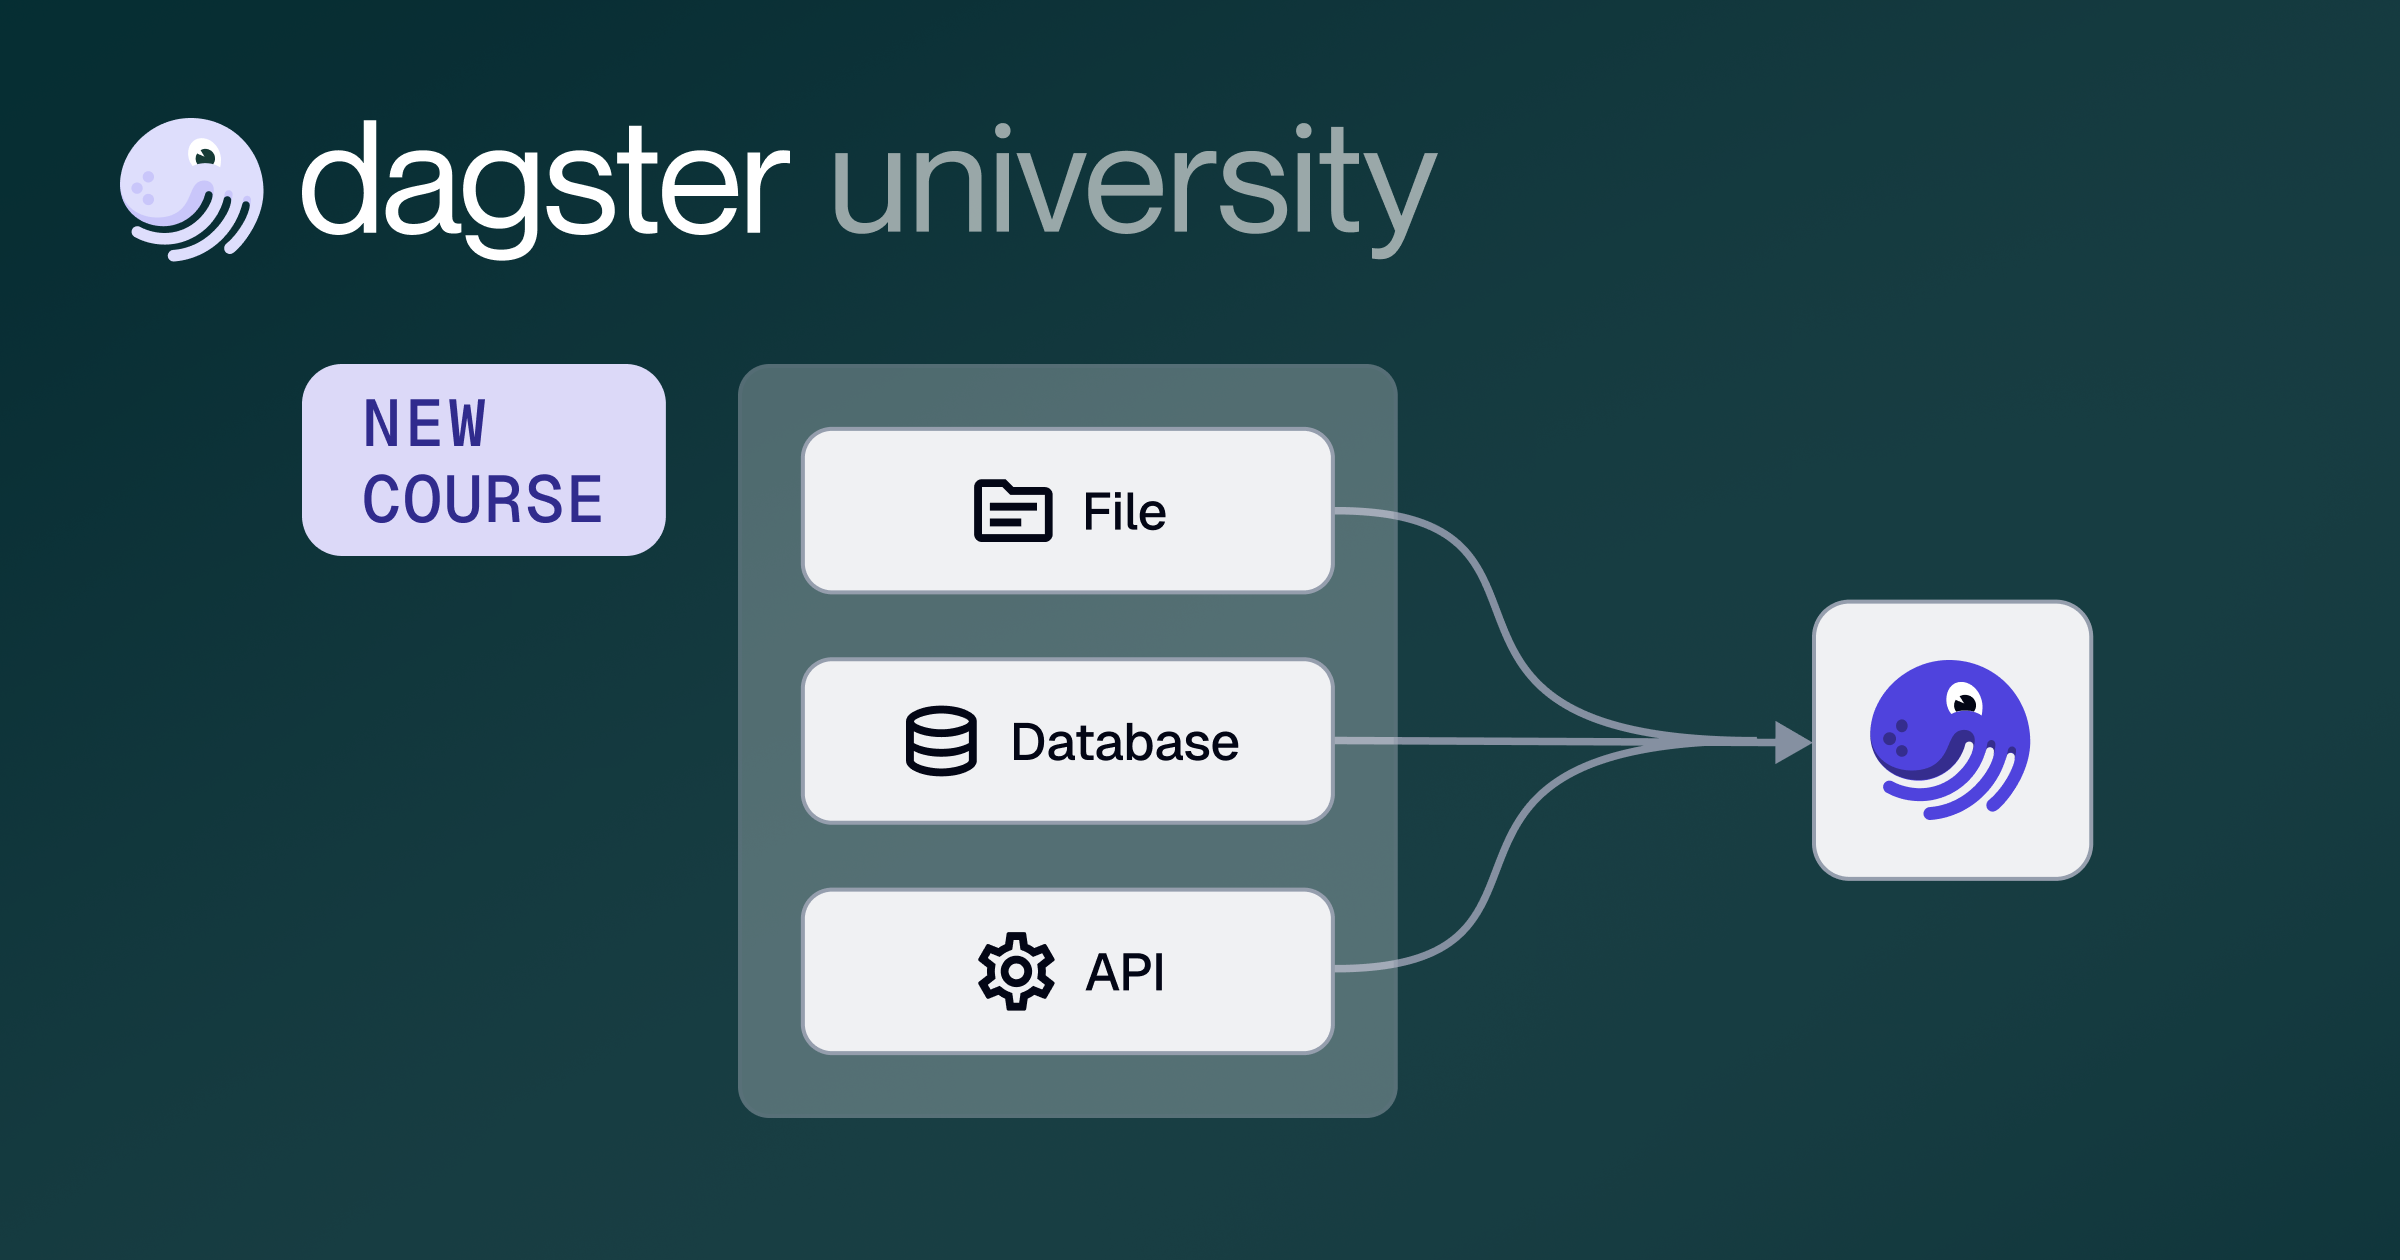
Dagster is excited to announce the launch of ETL with Dagster, a comprehensive seven-lesson course. This free course guides you through practical ETL implementation and architectural considerations, from single-file ingestion to full-scale database replication
Significantly improved pipeline-building experience with Components and dg, enhanced orchestration capabilities, integration power-ups, and more.
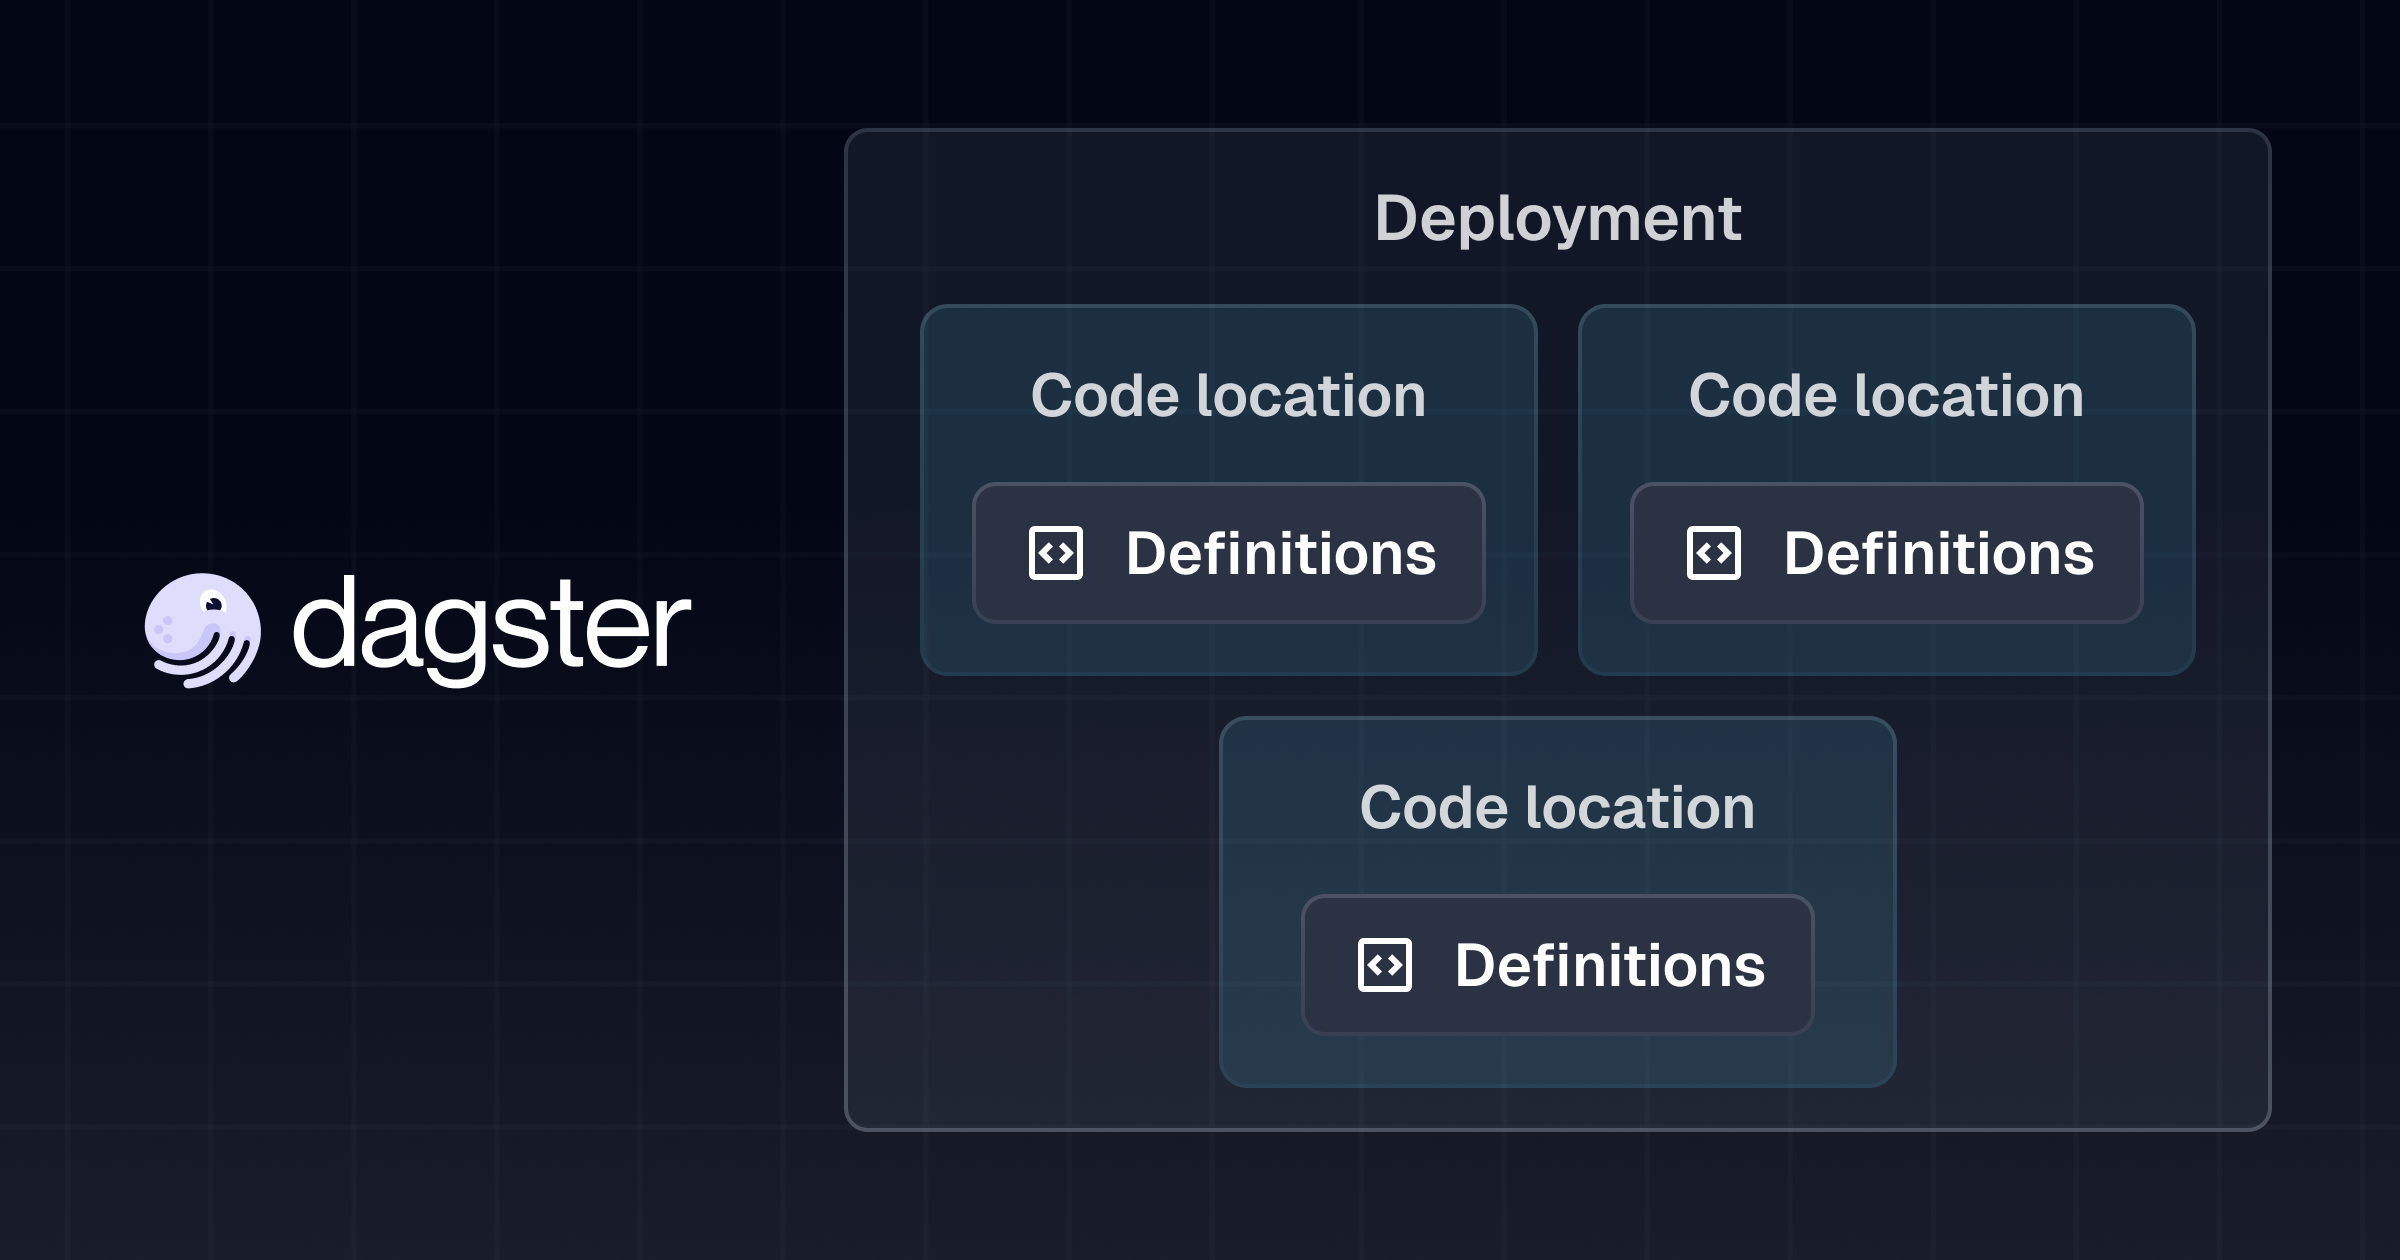
How to organize your code locations for clarity, maintainability, and reuse.
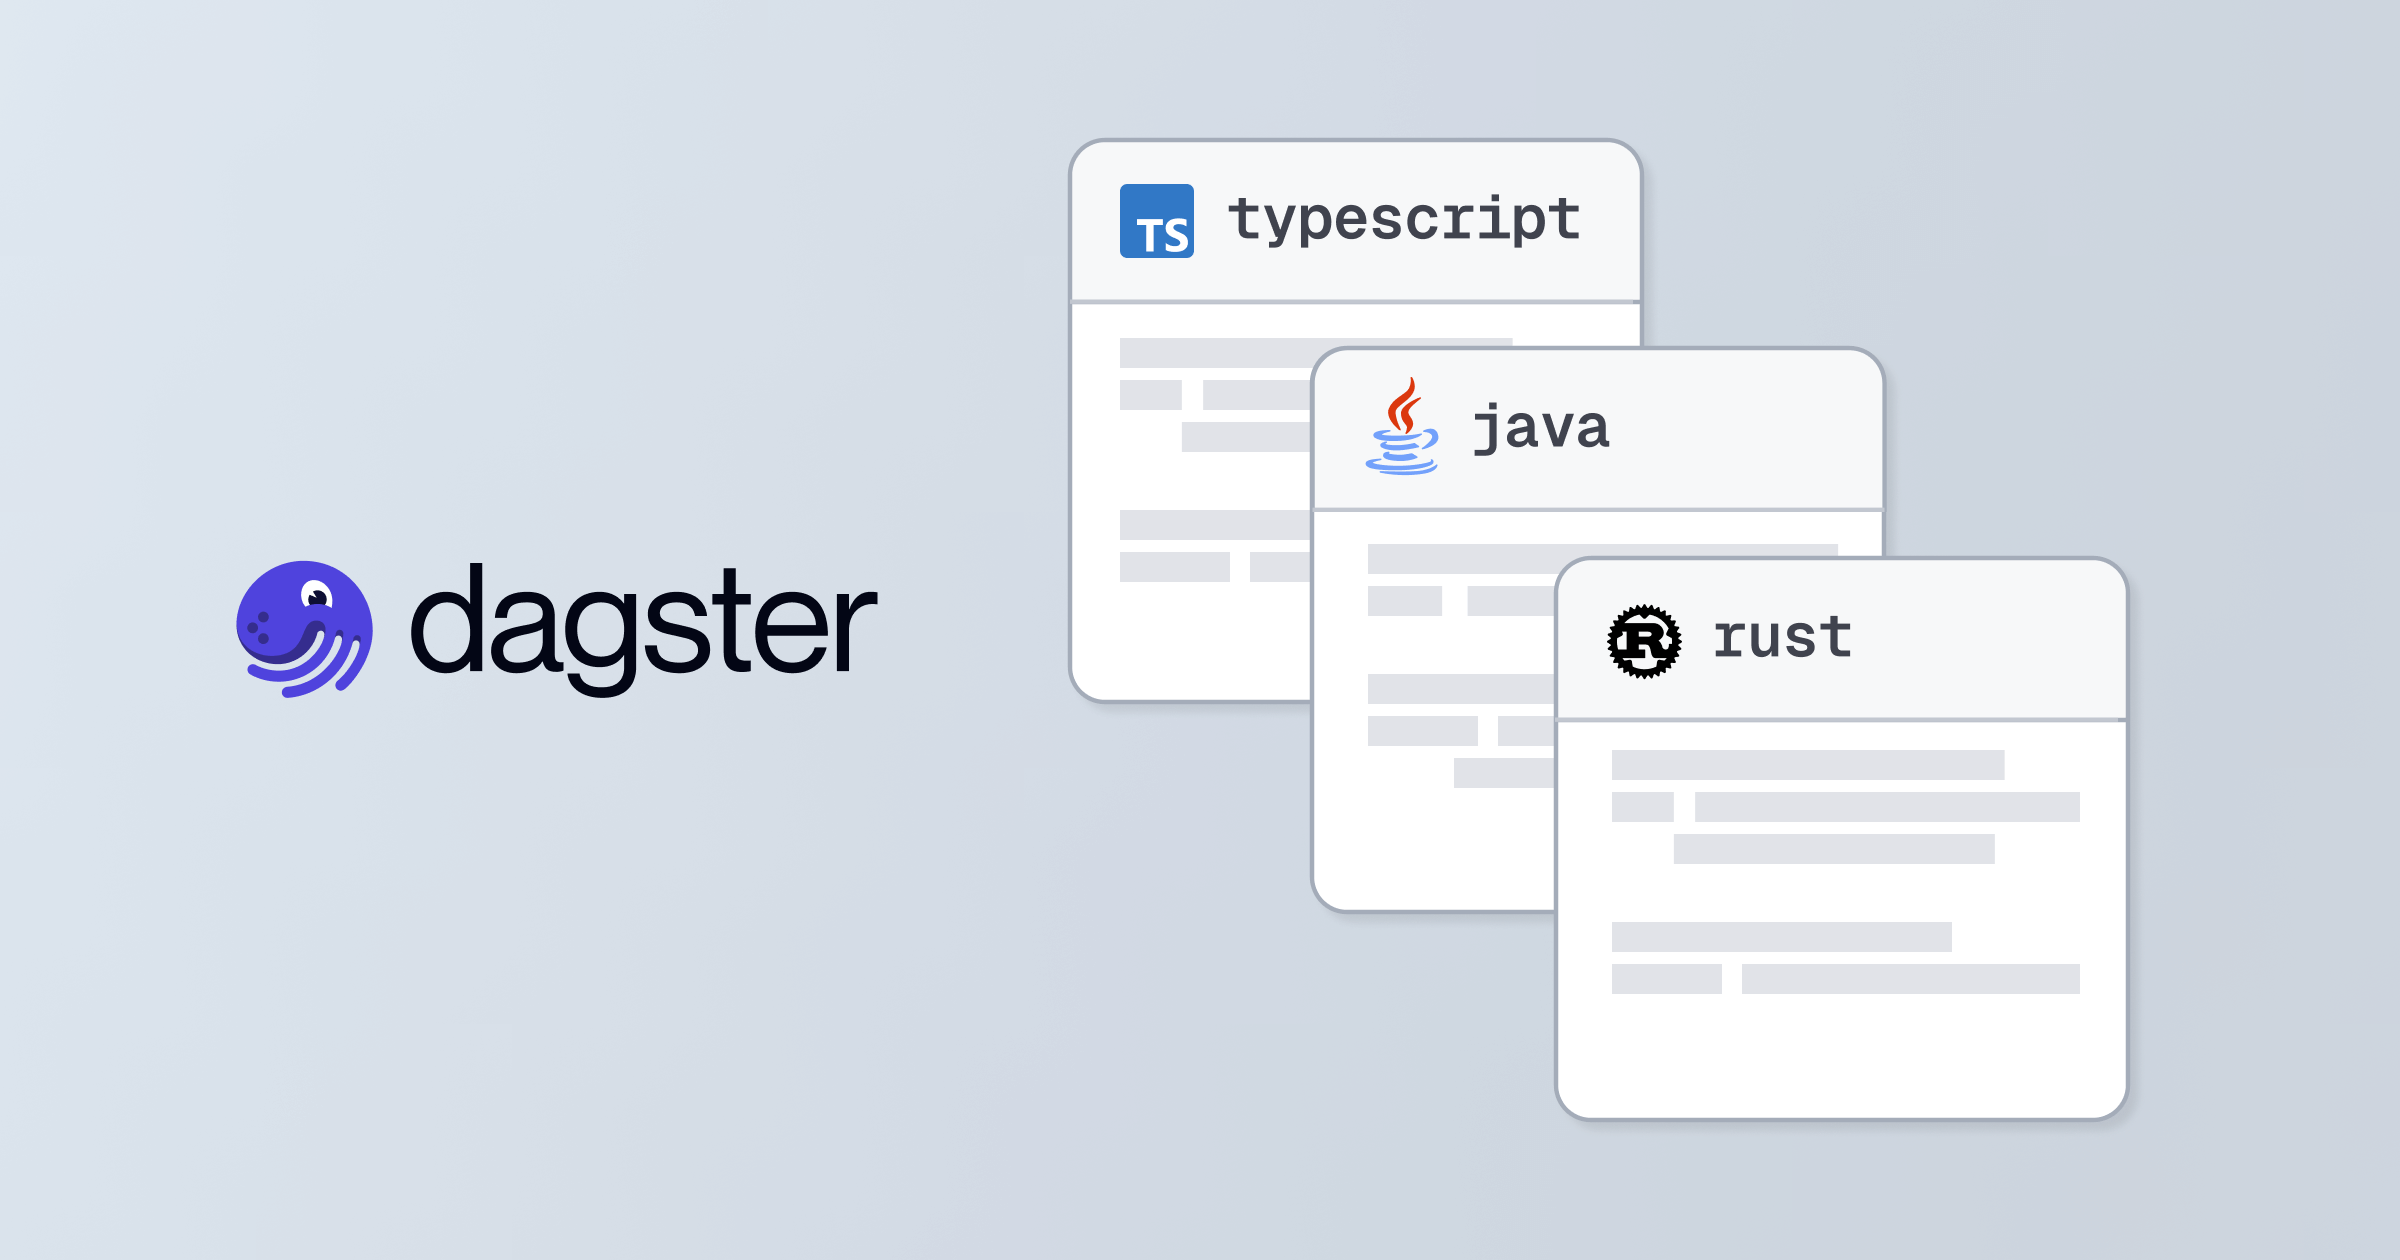
Expanding Dagster pipes to support Typescript, Rust, and Java
Data platforms can be complex, Dagster's understanding of Lineage makes it easy to get to whats important.
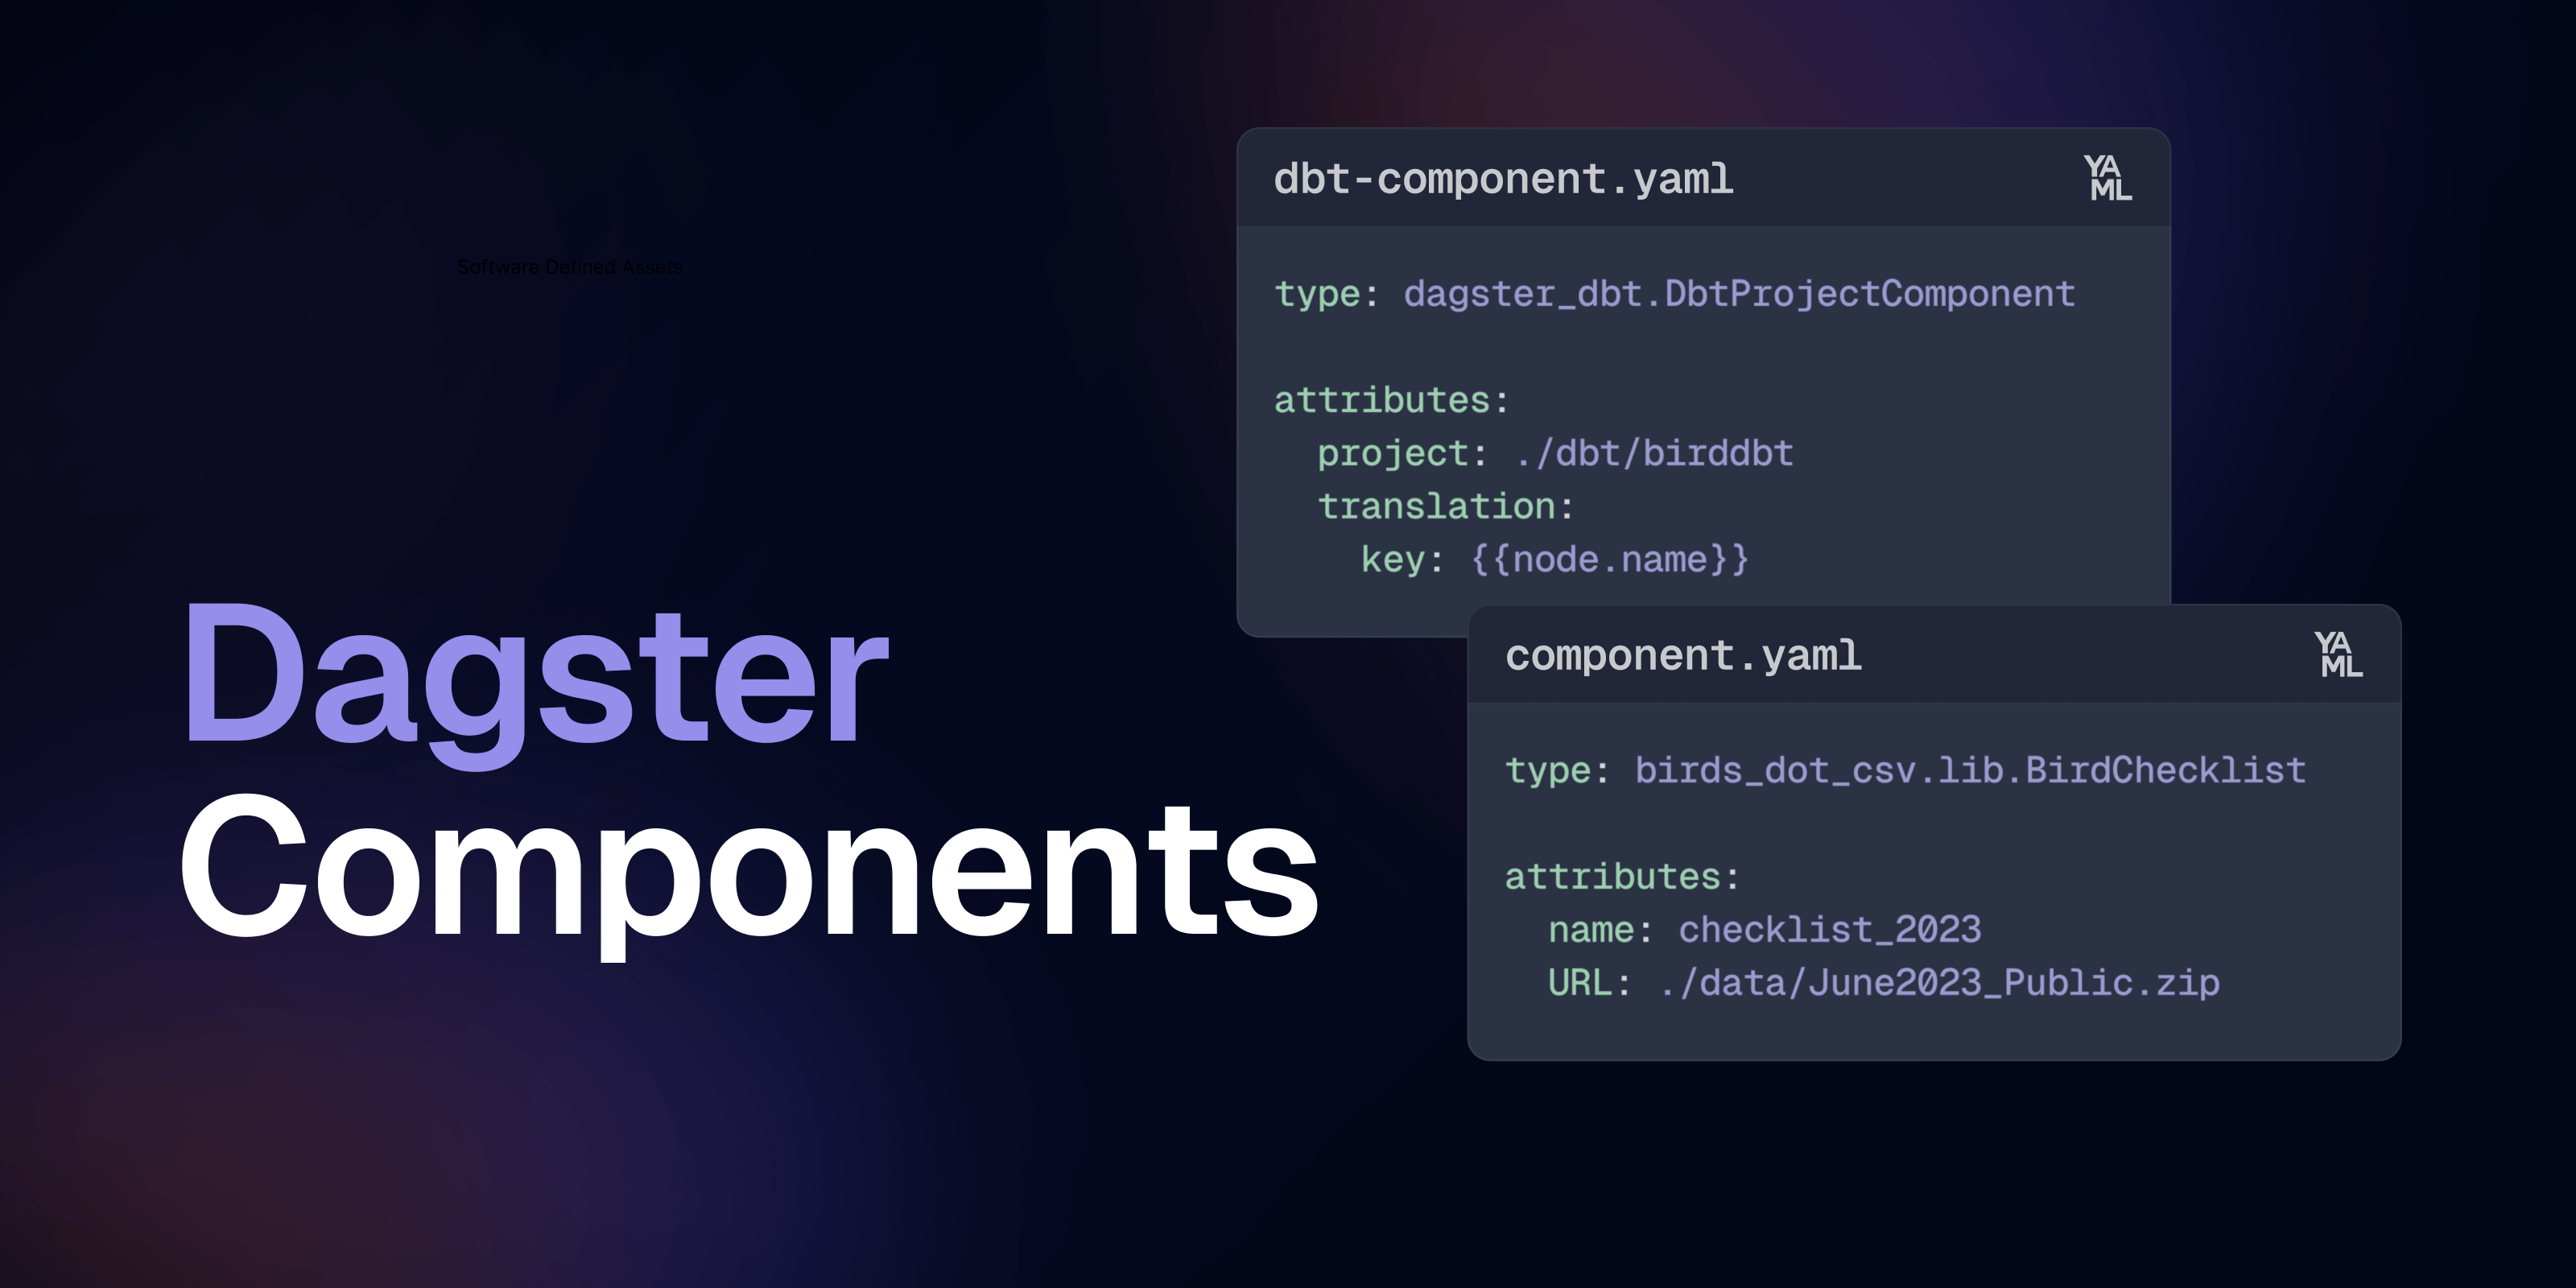
Introducing Dagster Components, a simplified approach to developing and managing your data pipelines
How we think about data orchestration needs to fundamentally change, and Dagster represents that shift in thinking.
You need tools that handle the trivial stuff and give you, your team, and your company space to think and act decisively.
The fundamental challenge facing data teams today is building scalable platforms that enable self-service for data consumers.
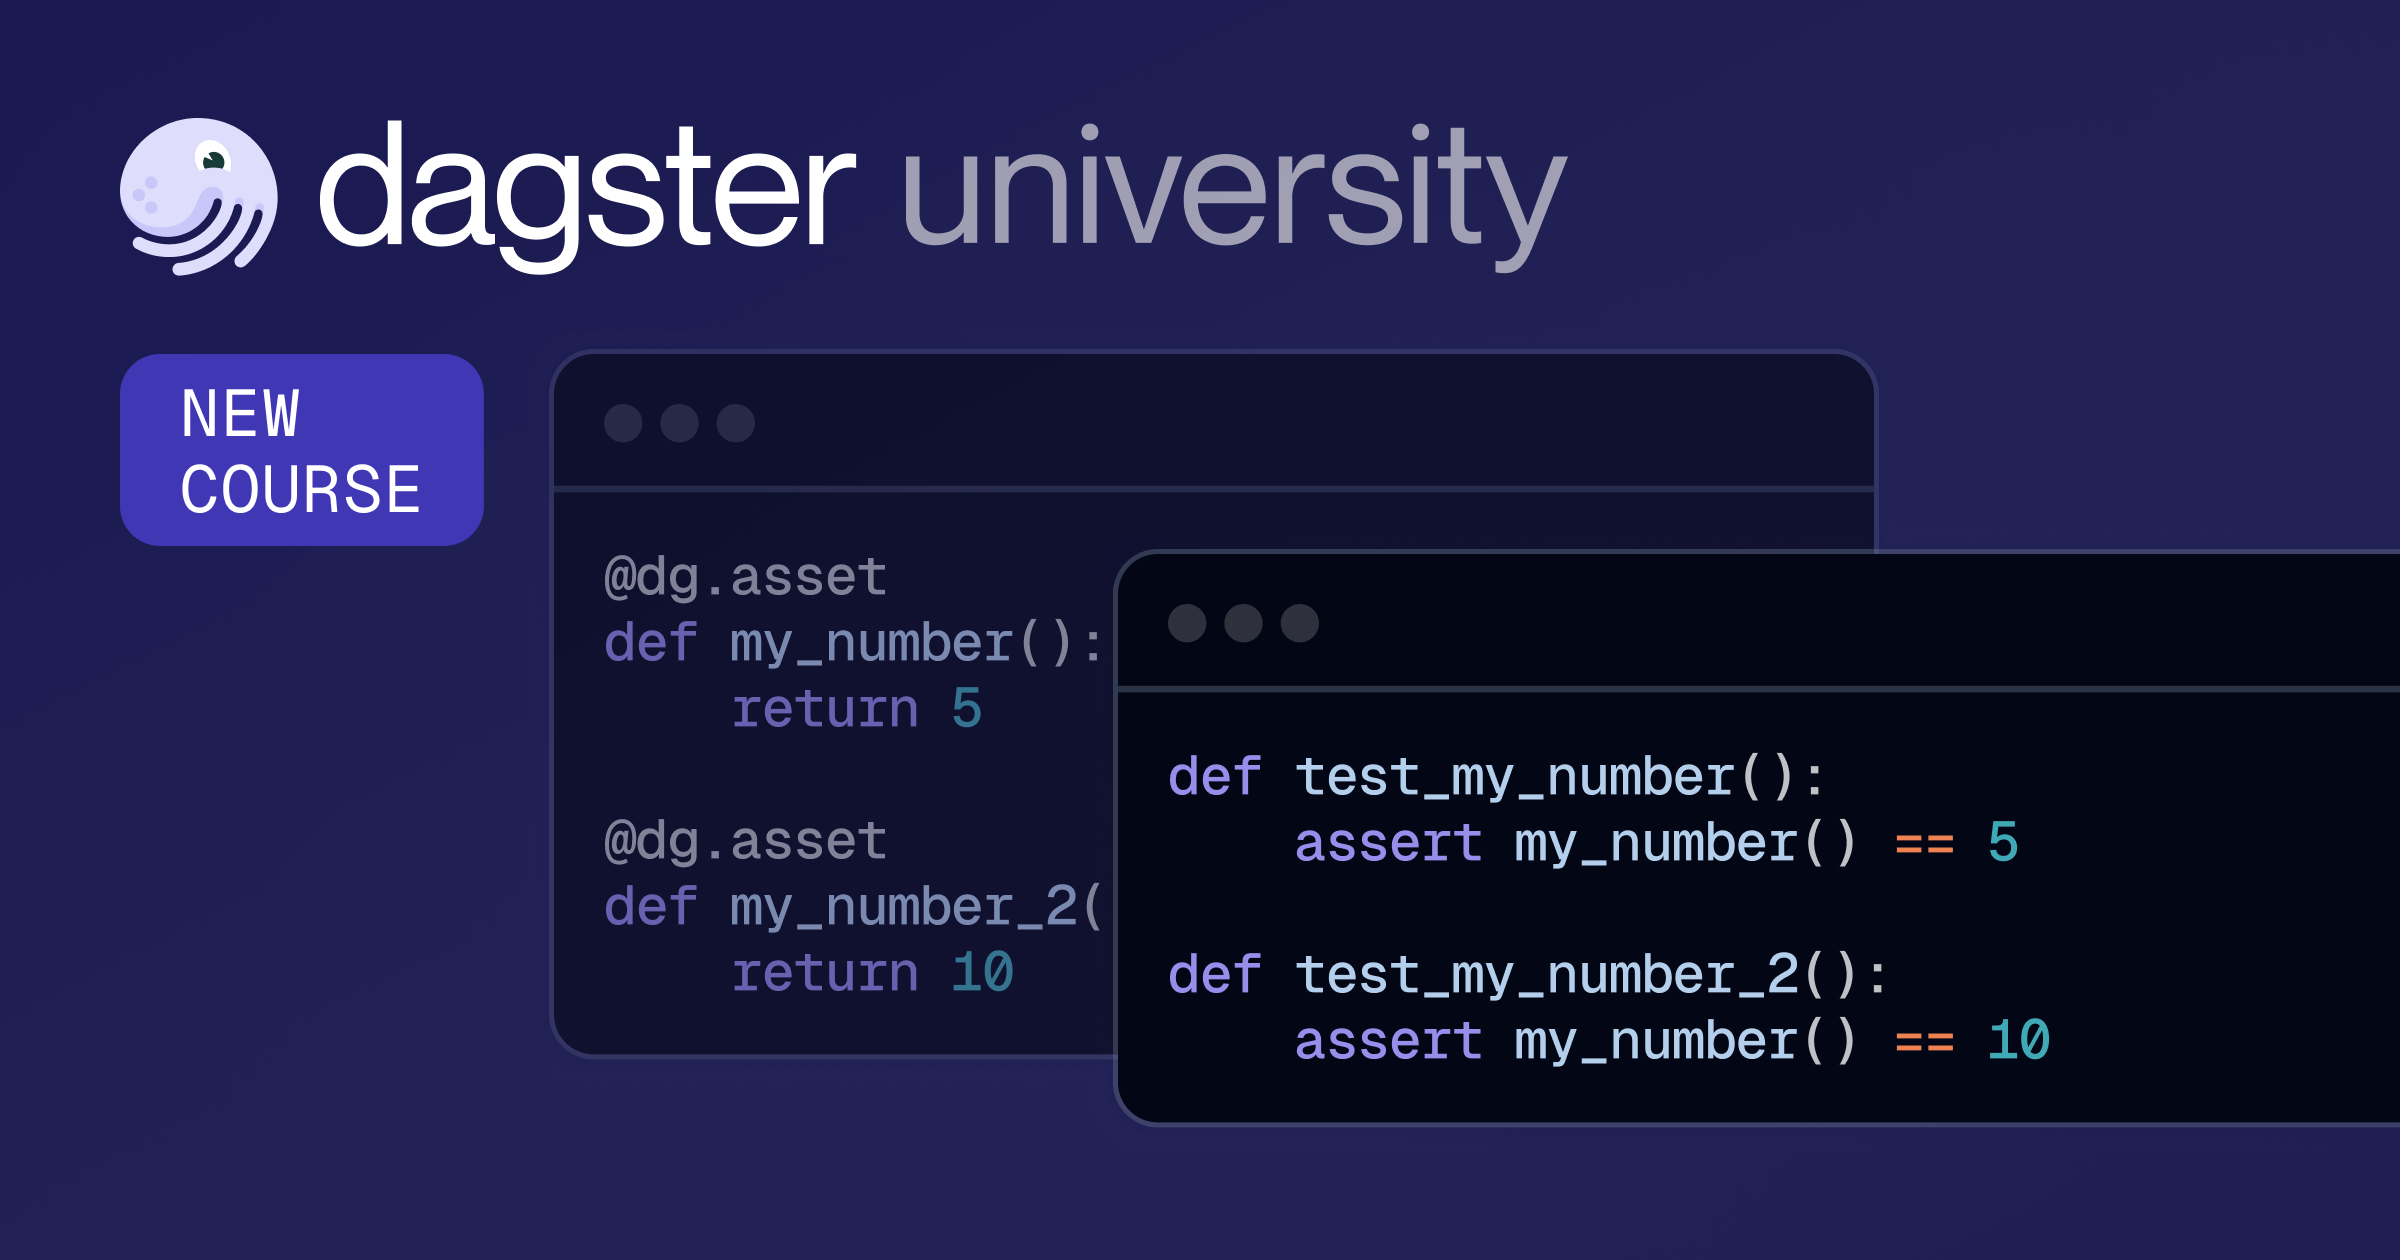
Learn best practices for writing Pythonic tests for Dagster.
Broken pipelines are unavoidable. Catch problems as soon as they happen with the improved alerting suite in Dagster+.
Intuitive Concurrency Controls, Improved ELT integrations, and Developer Experience Upgrades
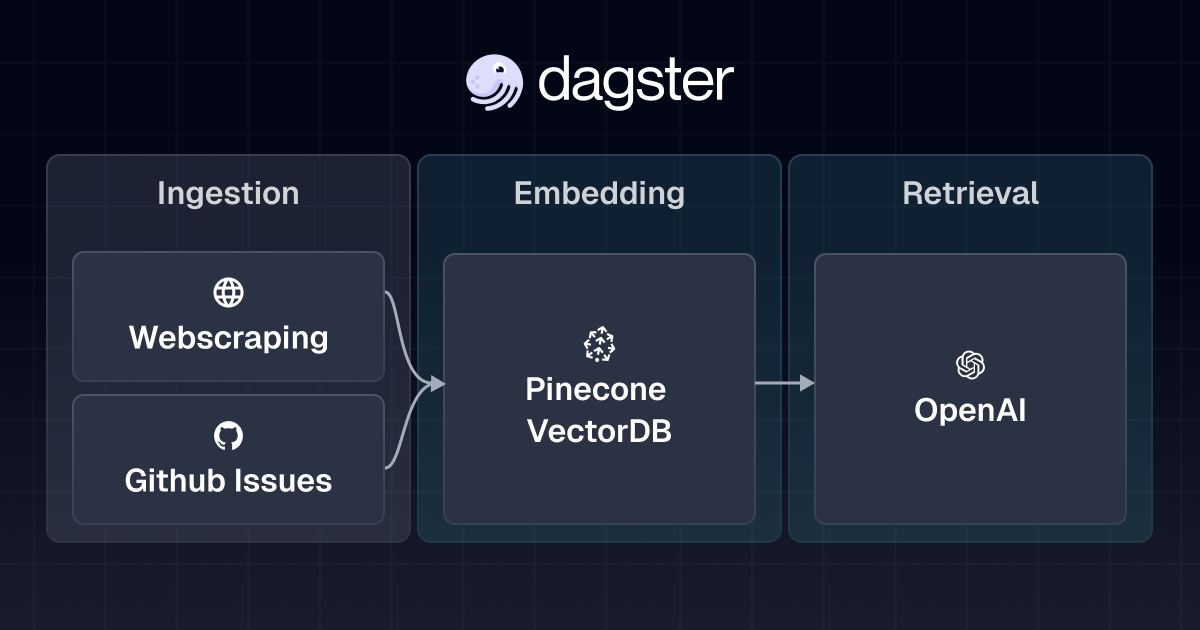
Modern AI development requires different patterns than traditional software. By combining familiar engineering practices with new approaches for handling the probabilistic nature of AI, teams can successfully scale their AI products into production.
Step-by-step guide to debugging Dagster code directly in Docker, bridging the gap between development and deployment.

Break down the silos between data engineering and BI tools
Declarative automation has officially graduated, BI in your asset graph, Airlift to streamline migrations, and more.
Expectations for Data Engineering will rapidly inflate; the nature of the work will change.
Navigate complex data environments more effectively, and ensure that valuable data assets are easily discoverable and usable.
No-code solutions sound easy – until they aren’t. Here’s why they often fail and what you can do about it for your data engineering.
AI engineering is data engineering. Here are 5 best practices the former should adopt from the latter to succeed.
Learn how to use Dagster and Modal to automate and streamline your machine learning model training and data processing.
How the next step in the evolution of the Data Engineering role requires a platform approach.
Get the tale of the tape between the two orchestration giants and see why Dagster stands tall as the superior choice.
The unseen data is often the deadliest. Here’s how to shine a light on it in your business.
Move past the MDS and build a data platform for observability, cost-efficiency, and top-tier orchestrating.
Dagster and SDF show how the power of two can connect local development and production orchestration.
Ecosystem and integration improvements, data catalog improvements, new asset checks, new declarative automation, and more.
Explore the importance of data quality and learn strategies for integrating quality checks using Dagster.
Operations Lead Eunice Ho dives into the Dagster Labs culture and why it makes for an ideal work environment.
Use Dagster and GX to improve data pipeline reliability without writing custom logic for data testing.
Why running data ingestion jobs straight from the orchestrator is often a preferred approach.
Get to know the tool that sets the standard for modern data orchestration.
Leverage the power of LLMs while keeping the costs in check using the Dagster OpenAI integration.
Use Asset Factories within Dagster to streamline data asset creation, promote code reusability, and maintain data engineering workflows.
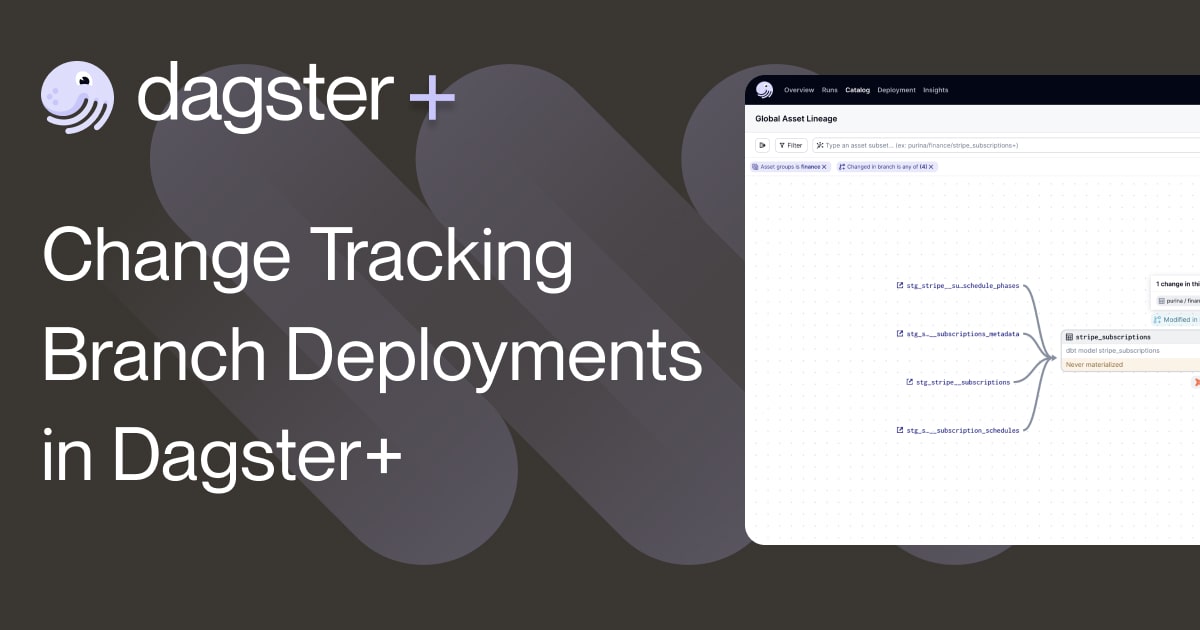
Dagster+ further enhances identification and collaboration around changes to your data pipelines.
Give your data teams a powerful new system of record without the overhead of maintaining a third-party catalog.
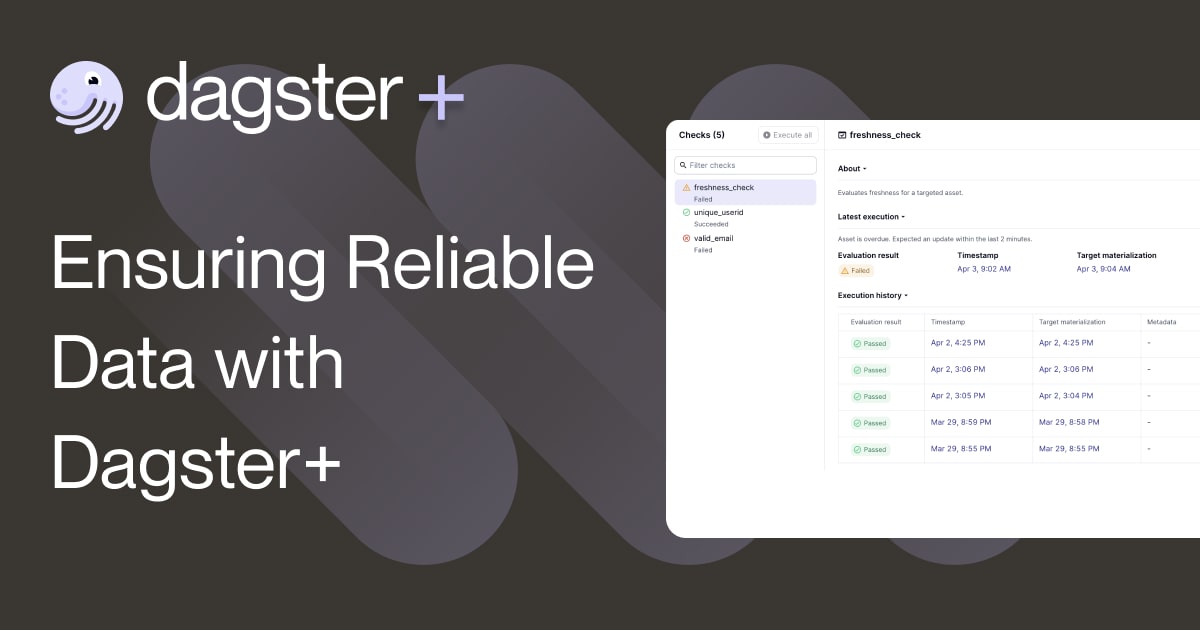
Dagster+ helps you monitor the freshness, quality, and schema of your data.
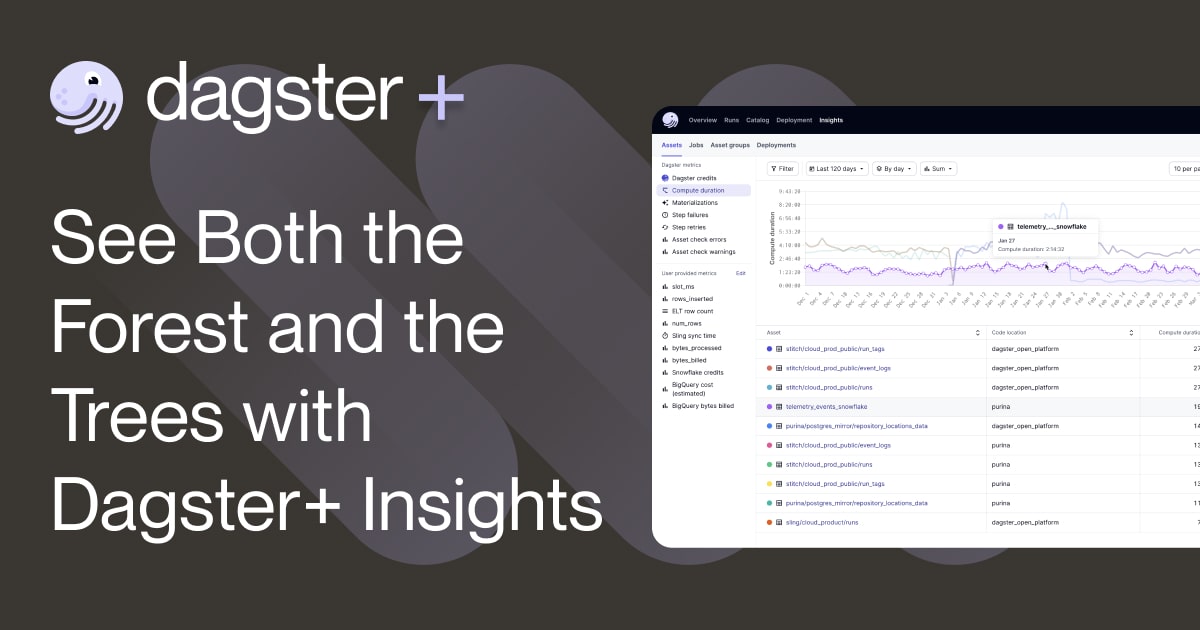
How Dagster+ Insights helps you control costs and elevate your data platform’s observability.
A case for asset-oriented over workflow-oriented in data orchestration.
A major set of updates to Dagster Core ahead of our Dagster+ launch.
We now have an officially supported dlt integration.
How we saved $40k and gained better control over our ingestion steps.
Learn the fundamentals of a healthy data engineering lifecycle to optimize pipeline and asset production.
The new dagster-openai integration lets you tap into the power of LLMs in a cost-efficient way.
Learn how organizations can harness the strengths of both approaches to optimize their data operations.
By implementing DSLs, data teams can open their data platform to many more users without compromising on standards.

How to develop data pipelines using Software-defined Assets.
The beliefs that organizations adopt about the way their data platforms should function influence their outcomes. Here are ours.
Major UI enhancements, Dagster Pipes upgrades and of course, dark mode :-)
We’re excited and humbled to bring the Retain.ai organization into our fold to help build out Dagster’s data orchestration capabilities.
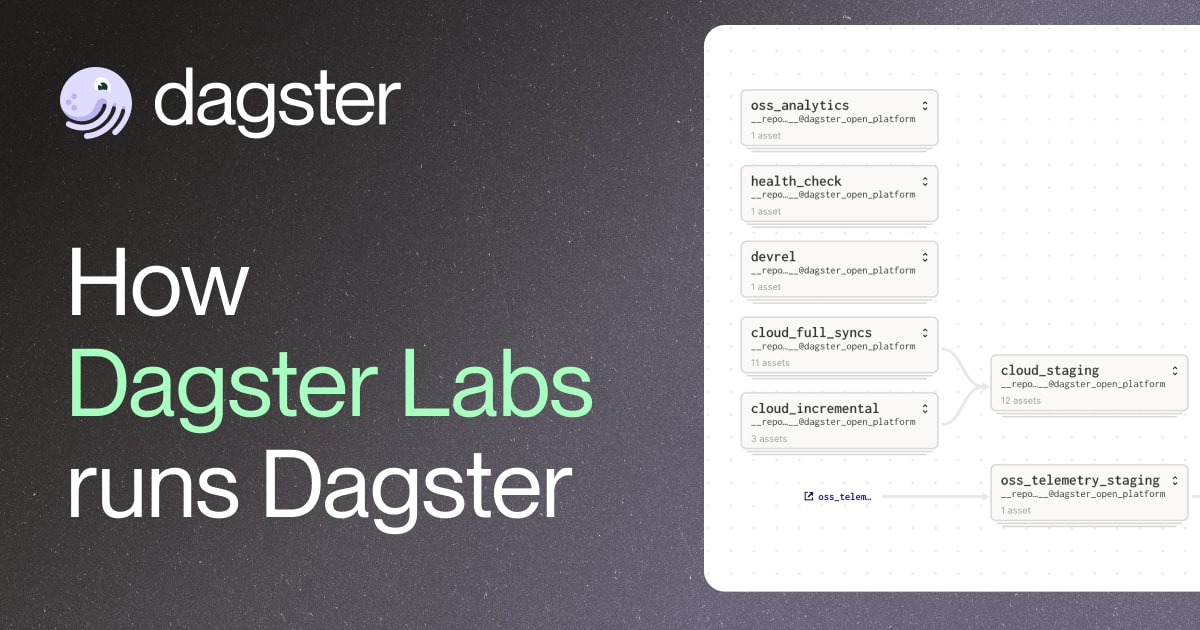
A technical deep dive into the patterns and implementations of the Dagster Open Platform using our open-sourced code and dbt models.
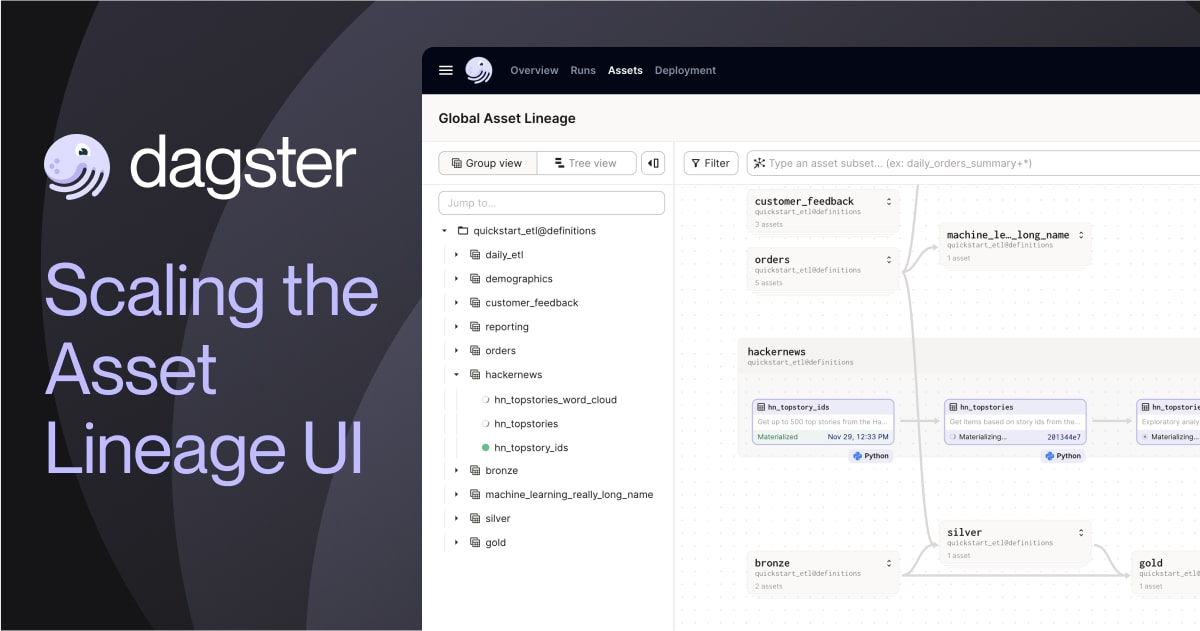
How the Dagster frontend team rapidly scaled Dagster’s DAG visualization for enterprise-sized data asset graphs.
Learn how to optimize your Python data pipeline code to run faster with our high-performance Python guide for data engineers.
Load messy data sources into well-structured tables or datasets, through automatic schema inference and evolution.
Learn how to automate data pipelines and deployments by integrating Git and CI/CD in our Python for data engineering series.
Use Dagster’s External Assets feature for data observability, lineage, data quality, and cataloging while bringing your own orchestration and scheduling.
A new protocol and toolkit for integrating and launching compute into remote execution environments from Dagster.
Solve data ingestion issues with Dagster's Embedded ELT feature, a lightweight embedded library.
Learn Dagster essentials and build asset-based data pipelines with Dagster University, our new self-guided course for beginners.
Gain operational observability on your data pipelines and bring cloud costs back under control with the Dagster Insights feature.
Deliver high-quality data with Dagster Asset Checks, the ability to embed data quality checks into your data pipeline.
Ahead of Launch Week, we are proud to be rolling out some exciting new capabilities.
We look at the write-audit-publish software design pattern used in ETL to ensure quality and reliability in data engineering workflows.
Launch Week kicks off October 9th with new functionality being shared each day. Our theme: Escaping the Modern Data Trap!
It is not every day you get to join a company working on building a product purpose-built for you.
We explore design patterns — reusable solutions to common problems in software design — as used in data engineering, specifically factory patterns in Python.
In the spirit of simplification, the company formerly known as Elementl is now doing business as Dagster Labs.
Learn how to use data engineering patterns and Dagster’s dynamic partitioning to build an outbound email report delivery pipeline.

In part VI of our Data Engineering with Python series, we explore type hinting functions and classes, and how type hints reduce errors.
In part V of our series on Data Engineering with Python, we cover best practices for managing environment variables in Python.
Dagster Labs founder Nick Shrock is interviewed by Rittman Analytics founder Mark Rittman
Orchestrate dbt with Dagster’s popular dbt integration, now with major enhancements to supercharge your dbt models as part of your data pipeline.
dbt docs slow? See how we dropped page load time and memory usage for a large dbt project by 20x using React Server Components.
The latest release brings major new dbt capabilities, new asset materialization controls, and more.
Elementl CEO Pete Hunt shares the three priorities that guide how we will evolve Dagster.
A step-by-step guide to using backfills and partitions to make data management more simple for data & ML engineers.
We are pleased to announce Elementl's $33M Series B and share our vision for what's next for Dagster and the practice of data engineering.
A recap of our live event on the benefits and techniques for orchestrating analytics pipelines.
Dagster’s dynamic partition definitions allow engineers to use the power of partitions in a broader range of scenarios.
Recent enhancements allow Dagster to surface clearer and more actionable errors to accelerate your development cycles.
Raising the quality bar requires process adjustments and a cultural shift.
Dagster 1.3 officially inducts Pythonic Config and Resources and brings new enhancements to Software-Defined Assets, integrations, documentation, and guides.
In part IV of our series, we explore setting up a Dagster project, and the key concept of Data Assets.
Major ergonomic improvements are coming to Dagster's config and resources systems, including a Pydantic frontend.
We cover 9 best practices and examples on structuring your Python projects for collaboration and productivity.
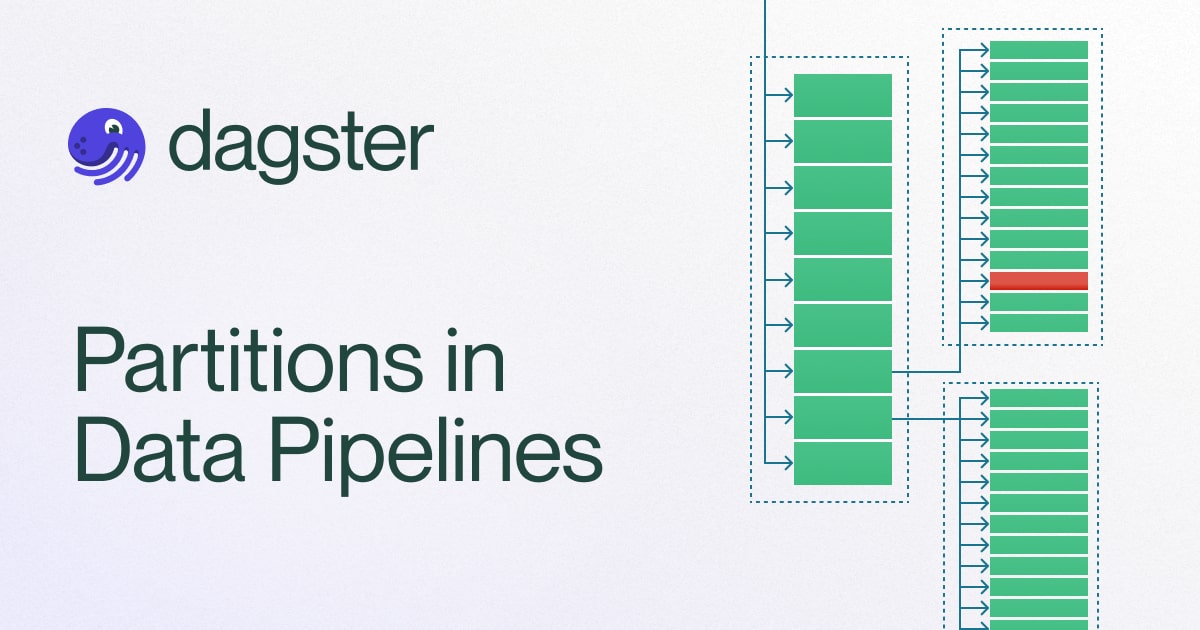
Partitioning is a technique that helps data engineers and ML engineers organize data and the computations that produce that data.
It's easy for an open-source project to buy fake GitHub stars. We share two approaches for detecting them.
Enhanced partitioned asset support and the introduction of Pythonic config and resources, and integration updates.
Using pex, Serverless Dagster Cloud now deploys 4 to 5 times faster by avoiding the overhead of building and launching Docker images.
The foundation of a solid Python project is mastering modules, packages and imports.
An introduction to managing Python dependencies and some virtual environment best practices.
In this tutorial, we tap into the power of OpenAI's ChatGPT to build a GitHub support bot using GPT3, LangChain, and Python.
A major release with Declarative Scheduling, multi-asset scheduling, and SDA partitioning. Plus Secrets management, Dagit enhancements, Integrations updates and more...
To be a more productive software engineer you need to master changes, how these affect the program and others on the team.
A total beginners tutorial in which we store REST API data in Google Sheets and learn some key abstractions.
What we learned when we introduced dynamically typed code to a large Python codebase, bringing Dagster's public API to 100% type coverage.
How to use Dagster’s open source data orchestrator to build machine learning pipelines and train ML models.
DuckDB is so hot right now. Learn how to build a data lake from dbt using DuckDB for SQL transformations, along with Python, Dagster, and Parquet files.
See how much easier you can collaborate using DuckDB’s high-powered cloud version MotherDuck to build a one-system data lake.
Data practitioners waste time writing unit tests to catch bugs they could have caught with smoke tests.
A tale of overstretched logs, counterintuitive web worker behavior, and ultimately a troublesome cursor issue.
If you are looking to get up and running with Dagster in 10 minutes or less, this is a good place to start. Buckle up.
When lots of event logs must be stored and indexed, Kafka is the obvious choice. Naturally, our queue runs on Postgres.
It’s not uncommon for a data engineer to devote 80% of their day to debugging. Dagster radically improves on this.
The enterprise orchestration platform that puts developer experience first: hybrid or serverless deployments, native branching, and out-of-the-box CI/CD.
Announcing Dagster 1.0. - a stable foundation for building the orchestration layer for modern data platforms.
The relationship between Dagster, the open-source project, and Dagster Cloud, our hosted SaaS platform.
Elementl, the company behind the Dagster data orchestration tool achieves SOC2 compliance.
The release of Dagster 1.0 and the GA launch of Dagster Cloud represent major milestones in the evolution of our orchestration solution.
Pete Hunt discusses what caused him to make the leap from Twitter to Elementl.
The Unbundling of Airflow' argued that modern data stack solutions (data ingestion, data transformation, reverse ETL) manage their own data orchestration. Data teams need is a control plane for the modern data stack.